Guide · Search & RAG
Jev as a reranker: an honest negative
Jason Zhu tested Jev reranking on 164 real queries.
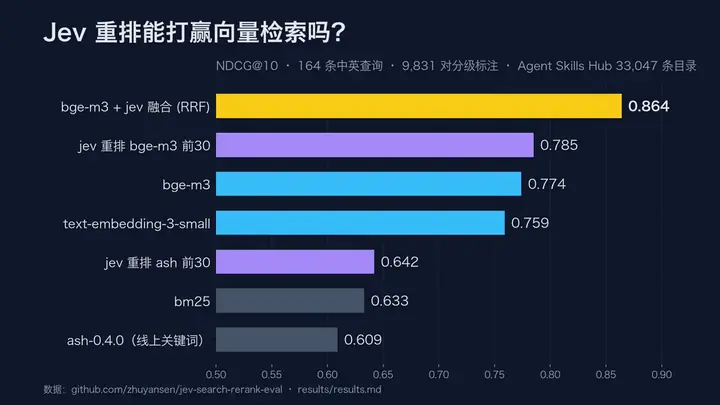
Open x.com ↗拿 Jev 做搜索重排,我先泼一盆冷水:单独用,它没打赢向量检索
TypeSafe 的 Jev 这阵子很火,一堆项目拿它做重排。我们在 Agent Skills Hub 的 33,047 条目录上认真测了一次,164 条中英文真实查询,9,831 对分级标注,整套只花了 2.6 美元
三个结论
01|单独重排,约等于没赢
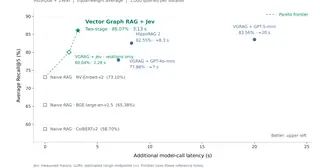
Jev 重排 bge-m3
How builders describe it
Jason Zhu tested Jev reranking on 164 real queries. Alone it did not clearly beat vector search; fused with it, it did. In Chinese.
A measured search reranking run over 33,047 catalog entries, 164 real queries, and 9,831 labelled pairs, reporting how Jev compares with BM25 and bge-m3.
The decision Jev makes
Rank candidates against a query, or answer whether a passage is relevant.
Where it fits
Search pipelines retrieve too much. These projects use Jev as a reranker or relevance check after the first search, so only useful results reach the user or the model. All 108 search & rag projects →
Related projects
 Search & RAGjev-keyboardJev-powered candidate reranking for Rime on macOS, with Windows support planned.GitHub · ★ 4 · Ideny42
 Search & RAGSmart FindCtrl+F, but for questions.GitHub · ★ 1 · eduardoalba00
 Search & RAGRepoFinderFind your way around a large open-source repo: architecture map plus "where is X implemented?" answers with line citations; optional TypeSafe Jev…GitHub · SelmanBoraySearch & RAGagent-doc-searchPoint coding agents at the right docs in large codebases: local BM25 and a TypeSafe Jev Choice search propose documents, then a Jev yes/no check…GitHub · beqauxSearch & RAGFilmHunchSelf-hostable movie finder: describe a film any way you like and TypeSafe Jev scores film cards and full profiles against your exact sentence.GitHub · eduardoalba00
 Search & RAGVector Graph RAGGraph RAG framework over Milvus vector search with no graph database required: Jev Noul judgments select graph relations and rerank full source…GitHub · ★ 258