Repo · Search & RAG
jev-assist
Don't burn your expensive main model on grep-and-guess grunt work — let jev rank the whole repo, and save the main model for reading the right files…
Open github.com ↗From the repository
Don't burn your model's context on a search flood — pipe it in and read above the cut line: one calibrated number per candidate, ~30 rows whether the pool is 40 or 4,000. It doesn't search; it decides what each hit is.
agent-skillclaude-codecode-reviewcontext-engineeringdeveloper-toolsjevtypesafe
How builders describe it
Don't burn your expensive main model on grep-and-guess grunt work — let jev rank the whole repo, and save the main model for reading the right files and writing the right code.
A CLI that takes the output of grep, git ls-files or a test run and returns each candidate line with a calibrated score, sorted, with an exact total and a cut line you read above.
The decision Jev makes
Rank candidates against a query, or answer whether a passage is relevant.
Where it fits
Search pipelines retrieve too much. These projects use Jev as a reranker or relevance check after the first search, so only useful results reach the user or the model. All 108 search & rag projects →
Related projects
 Search & RAGjev-keyboardJev-powered candidate reranking for Rime on macOS, with Windows support planned.GitHub · ★ 4 · Ideny42
 Search & RAGSmart FindCtrl+F, but for questions.GitHub · ★ 1 · eduardoalba00
 Search & RAGRepoFinderFind your way around a large open-source repo: architecture map plus "where is X implemented?" answers with line citations; optional TypeSafe Jev…GitHub · SelmanBoraySearch & RAGagent-doc-searchPoint coding agents at the right docs in large codebases: local BM25 and a TypeSafe Jev Choice search propose documents, then a Jev yes/no check…GitHub · beqauxSearch & RAGFilmHunchSelf-hostable movie finder: describe a film any way you like and TypeSafe Jev scores film cards and full profiles against your exact sentence.GitHub · eduardoalba00
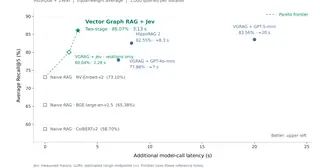 Search & RAGVector Graph RAGGraph RAG framework over Milvus vector search with no graph database required: Jev Noul judgments select graph relations and rerank full source…GitHub · ★ 258