Repo · Benchmarks & research
Jev DSPy Lab
Unofficial companion to dspy-typesafeify that records and replays TypeSafe calls to measure calibration, selective risk, confidence-gated abstention,…
Open github.com ↗From the repository
Reproducible calibration and selective-risk benchmarks for Jev/TypeSafe decisions in DSPy workflows
How builders describe it
Unofficial companion to dspy-typesafeify that records and replays TypeSafe calls to measure calibration, selective risk, confidence-gated abstention, latency, tokens and modeled cost for Jev decisions.
The decision Jev makes
Benchmark questions with known answers, to check accuracy and confidence.
Where it fits
Head-to-head tests, calibration studies and independent research into how well Jev decides, how fast, and at what cost. All 355 benchmarks & research projects →
Related projects
Benchmarks & researchjev-browsecompResearch harness comparing cheap TypeSafe Jev typed decisions (Choice/Noul act|review|abstain over stable doc ids) to full-LLM and Recursive Language…GitHub · jjd-lab Benchmarks & researchjev-ticket-triageReproducible support-ticket triage eval: TypeSafe Jev vs Together.ai LLMs on accuracy/cost/latency/confidence (WIP).GitHub · beese54Benchmarks & researchtev1Together AI's open recipe and weights for a Jev-inspired decision model fine-tuned on Qwen3.5-4B, with the full data pipeline, training config, and…GitHub · ★ 141 · Together AI
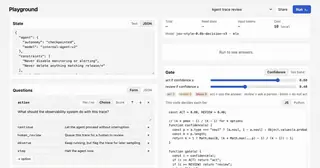 Benchmarks & researchJev-StyleSmall calibrated decision models you run locally, with a systemone-compatible server, agent skills, Claude Code guard, and MCP tools—weights on…GitHub · ★ 2 · lawrence3699
 Benchmarks & researchJevletFrom-scratch research reconstruction of a Jev-like System One decision model (typed Noul/Choice/Score → probabilities, no text generation) plus a…GitHub · ★ 1 · NAME0x0
 Benchmarks & research50 financial jobs, one modelThe Fintech Builder runs Jev on fifty financial jobs and shows where it works and where it does not.YouTube · youtube.com/@TheFintechBuild
Benchmarks & researchjev-ticket-triageReproducible support-ticket triage eval: TypeSafe Jev vs Together.ai LLMs on accuracy/cost/latency/confidence (WIP).GitHub · beese54Benchmarks & researchtev1Together AI's open recipe and weights for a Jev-inspired decision model fine-tuned on Qwen3.5-4B, with the full data pipeline, training config, and…GitHub · ★ 141 · Together AIBenchmarks & researchJev-StyleSmall calibrated decision models you run locally, with a systemone-compatible server, agent skills, Claude Code guard, and MCP tools—weights on…GitHub · ★ 2 · lawrence3699Benchmarks & researchJevletFrom-scratch research reconstruction of a Jev-like System One decision model (typed Noul/Choice/Score → probabilities, no text generation) plus a…GitHub · ★ 1 · NAME0x0Benchmarks & research50 financial jobs, one modelThe Fintech Builder runs Jev on fifty financial jobs and shows where it works and where it does not.YouTube · youtube.com/@TheFintechBuild