17 · 682 projects
Jev for benchmarks & research
Head-to-head tests, calibration studies and independent research into how well Jev decides, how fast, and at what cost.
What Jev decides: Benchmark questions with known answers, to check accuracy and confidence.
Projects, newest first
 Benchmarks & researchMicaA 4B decision model: calibrated probabilities for yes/no, choice and score questions over long inputs.GitHub · ★ 37 · akivet
 Benchmarks & researchawesome-jev-papers📄 Research papers on Jev, TypeSafe's System One model, and the open models built in its shape.GitHub · ★ 5 · OmniJev
 Benchmarks & researchjev-typesafe-real-financial-use-casesFifty real-world financial use cases for TypeSafe's Jev model: typed, structured LLM answers over ledgers, fraud, portfolios, trades and filings,…GitHub · ★ 3 · IslamBaraka90
 Benchmarks & researchjev-healthcare-labOpen experiment comparing TypeSafe Jev vs DeepSeek on 96 healthcare tasks across 12 scenarios (quality, latency, cost) with per-task data and…GitHub · JuneYaooo
 Benchmarks & researchtypesafe-jev-ecosystemExplore the TypeSafe Jev ecosystem: open-source integrations, compatible decision models, SDKs, agent tools, and research.GitHub · ★ 4 · VoltAgent
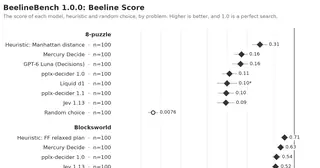 Benchmarks & researchBeelineBenchHow well do decision models plan across a multi-step problem?GitHub · ★ 3 · kyle-pena-nlp
 Benchmarks & researchjevbench (Leanmcp)Open framework and dataset for benchmarking typed decision models (Jev 1.13, Liquid D1, djev, Laya, Clef, pplx-decider and others) across science,…GitHub · ★ 2 · Leanmcp
 Benchmarks & researchFastJEVOfficial inference code for FastJEV, a training-free approach to compact candidate evaluation in JEV models.GitHub · ★ 2 · JieMaMagic
 Benchmarks & researchjev-benchConfigurable classifier workbench for repeatable latency and accuracy experiments on TypeSafe Jev (Banking77 accuracy, OpenRouter comparisons) with a…GitHub · ★ 1 · cocodedk
 Benchmarks & researchDexAn open-source, Jev-compatible decision model on an Ettin-1B encoder.GitHub · ★ 1 · CanadaOrNaw
 Benchmarks & researchjev-playground (Ahmar004)A fun and interactive playground to play with Jev and make Jev and frontier LLMs do the same tasks, to learn the use cases of Jev in a fun and…GitHub · ★ 1 · Ahmar004
 Benchmarks & researchBLADEPaper code for failure attribution in LLM multi-agent systems: every dependency and contract-audit judgment is a multiple-choice question answered by…GitHub · GXG-CS
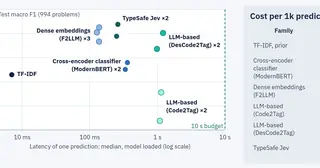 Benchmarks & researchcodeforces-tag-predictionResearch benchmark for multi-label tagging of Codeforces problems comparing TypeSafe Jev against zero-shot LLMs, fine-tuned encoders, dense…GitHub · msobroza
 Benchmarks & researchDecision Layer BenchmarkWhat an AI agent's decision layer (routing, prompt-injection, PII, permission, next step) costs on OpenAI, Anthropic, Google and TypeSafe Jev 1.13,…GitHub · GOhaike
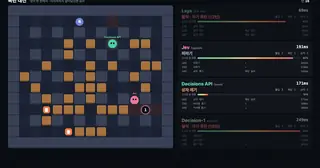 Benchmarks & researchDecision Model ArenaSide-by-side games and questions for four decision models—OpenAI Decisions API, Microsoft Decision-1, TypeSafe Jev and local Laya—with code owning…GitHub · dante01yoon
 Benchmarks & researchJev ArenaOpen-source web arena that runs live head-to-head challenges of TypeSafe Jev against Claude Opus 5.5 (trading, Tetris, lead race, review triage)…GitHub · AlanECE
 Benchmarks & researchJev RAG Chinese BenchmarkReproducible Chinese RAG reranking benchmark for TypeSafe Jev on C-MTEB/T2Reranking with a frozen protocol, pinned model, cost caps and full per-call…GitHub · vicfei
 Benchmarks & researchsnap-vs-jev-sweReproducible benchmark of fast decision models (SubQ Snap, TypeSafe Jev and three open models) on software-engineering tasks: SWE-bench Verified file…GitHub · kprzybysBenchmarks & researchTHX-01An open-source decision model with 322M parameters that runs on a phone.Site · doofz
 Benchmarks & researchjev-docs-benchmarksStudy documentation and benchmark for various Jev-like products (commercial and open source).GitHub · ★ 6 · akitaonrails
 Benchmarks & researchprivatemode-decisions-benchmarkEdgeless Systems' benchmark comparing its Privatemode Decisions library (GLM-5.3-Flash in an attested enclave) with TypeSafe Jev and local Laya on…GitHub · ★ 2 · edgelesssys
 Benchmarks & researchjev-deterministic-benchmark1,000-decision behavioral benchmark of Jev across 25 deterministic reasoning families.GitHub · ★ 2 · etsabaryBenchmarks & researchA decision model d1 surpasses JevGIGAZINE's report on Liquid AI's d1, which it describes as the first decision model to beat Jev on Hugging Face's Decision Index, and a short survey…GuideBenchmarks & researchtypesafe.aiA TypeSafe media piece arguing that RLHF-trained language models please humans and assist rather than make reliable autonomous decisions, and asking…Site · TypeSafe AIBenchmarks & researchBest Decision Model APIs in 2026A ranked comparison of thirteen decision-model APIs as of October 2026, including Jev, OpenAI Decisions, Clef, Liquid d1, Kev, Perplexity Decider,…GuideBenchmarks & researchLiquid AI d1Liquid AI's first decision model, a hosted API that adds image input to the Choice, Score, and Noul shape.SiteBenchmarks & researchPutting Jev in a Playwright testing loopA field report on putting Jev inside a Playwright browser-testing loop: two Jev calls per probe, 63 probes in 24.3 seconds, and a 131 ms median round…Guide · Jason Arbon
 Benchmarks & researchBespoke NimbleOpen recipe for a local Jev-style decision model: a Qwen3.5-9B LoRA that scores one allowed answer token per Choice, boolean or rubric Score…GitHub · ★ 2.2k
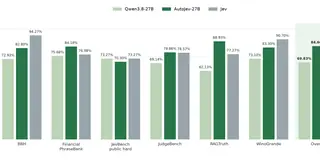 Benchmarks & researchAutoJevAn open recipe for a 27B multimodal decision model trained with full-weight SFT on 73,000 examples over one H200, serving choice, noul and score on…GitHub · ★ 132
 Benchmarks & researchlaya-AscendAscend NPU fork of the Laya decision checkpoints that answers Jev-style Choice, Score and Noul questions in a single forward pass on Huawei 910B…GitHub · ★ 110
 Benchmarks & researchbekko-system-oneSmall System One decision models (17M–400M) for Yes/No, Choice, and Score (independent open weights).GitHub · ★ 37 · hotchpotch
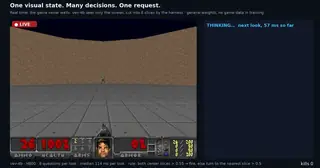 Benchmarks & researchvevOpen multimodal Jev-like decision models (text+images) speaking /v1/systemone on Qwen3.5 weights; self-host on your GPU.GitHub · ★ 17 · Xiaooolong
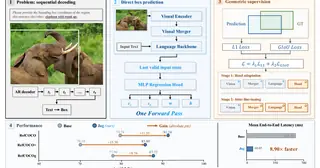 Benchmarks & researchJagJag, a Jev-inspired visual grounding model: a Qwen3.5-0.8B backbone plus a lightweight MLP predicts normalized cxcywh bounding boxes for an image and…GitHub · ★ 13
 Benchmarks & researchrulingTurns an open local chat model into a Jev-style decision engine served on /v1/systemone, with training, eval, and calibration commands; independent…GitHub · ★ 10 · bradAGI
 Benchmarks & researchtaiwan-sovereignty-decision-modelsScript-dependent answers about Taiwan in commercial decision models (OpenAI Decisions API, TypeSafe Jev, Cloudflare Clef): data, code, paper.GitHub · ★ 10 · pirrer
 Benchmarks & researchVisual-JevA Jev-style typed-decision baseline built on the frozen Qwen3.5-4B checkpoint that accepts a local image path directly, letting the vision-language…GitHub · ★ 9
 Benchmarks & researchJev Vs. Open AlternativesNotebook benchmark that compares Jev with open models and specialised tools on five document-pipeline chores: language detection (Choice(12)), page…GitHub · ★ 8
 Benchmarks & researchLuceOpen recipe for calibrated decision models: an LLM teacher writes training data from a one-sentence task description, a LoRA plus decision head on…GitHub · ★ 8
 Benchmarks & researchtalktojev (Jev Prime)Hosted chatbot with no language model in the loop: every word is chosen by TypeSafe Jev via the OpenRouter Decisions API (Choice over a vocabulary),…GitHub · ★ 6 · xucian
 Benchmarks & researchSystem-One-Control-BenchSystem-One Control Bench: can a non-generative decision model steer an agent across a small grid?GitHub · ★ 3 · Exemocaro
 Benchmarks & researchDecisionBenchAn open benchmark runtime for document-grounded decision models: it scores Jev Noul, Choice and Score answers on pinned tasks and counts malformed…GitHub · ★ 3
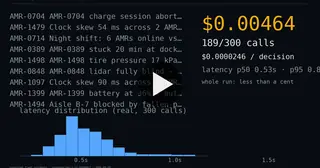 Benchmarks & researchJev for Physical AIMeasured robotics study that runs Jev as the decision layer for a 10,000-robot warehouse fleet over 41 bilingual incident templates and publishes a…GitHub · ★ 3
 Benchmarks & researchS1MBSystem One Mosaic Benchmark: a Python evaluator and Next.js viewer comparing Jev and open decision models across 137 English Choice, Noul and Score…GitHub · ★ 3
 Benchmarks & researchFlightBenchFixed-wing landing simulator where a human can compete against Jev: four Jev Choice decisions map to aileron, elevator, rudder and throttle commands…GitHub · ★ 2
 Benchmarks & researchJev Medhallu BenchmarkPre-registered benchmark adding Jev 1.13 to Stanford MedHELM's MedHallu results: one Noul asks whether a proposed answer misrepresents its PubMed…GitHub · ★ 2
 Benchmarks & researchJev Synthetic SurveyIndependent evaluation running Jev jev-1.13.0 and GPT-4.1 as the same 300 Twin-2K-500 synthetic survey respondents across 24,596 paired cells,…GitHub · ★ 2
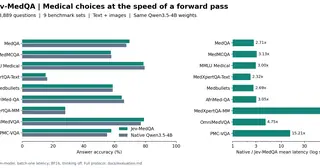 Benchmarks & researchJev-MedQAJev-style medical QA implementation on Qwen3.5-4B that selects an answer from candidates in one forward pass instead of generating text.GitHub · ★ 2
 Benchmarks & researchjev-judgePytest/Vitest-style CI evaluations of LLM and RAG outputs: declarative YAML tests (faithfulness, relevance, hallucination, guardrails) answered by…GitHub · ★ 1 · 00200200
 Benchmarks & researchJev Resume ScreeningReproducible recruiting cookbook that screens one resume against a job description in a single parallel Jev request of five Noul evidence gates, four…GitHub · ★ 1
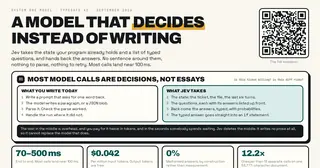 Benchmarks & researchjev-samplesRunnable samples for Jev, TypeSafe AI's System One model.GitHub · ★ 1 · aarora79
 Benchmarks & researchjev-fanout-benchReproducible billing measurement for TypeSafe Jev parallel questions: does one request with N questions bill the state once versus N separate…GitHub · blowxianBenchmarks & researchArchai Jev Zagreus 0.4B ItalianAn ultra-light Italian decision model: 400M Llama-based, a 465 MB Q8_0 GGUF, answering multiple choice with A–D tokens and booleans with TRUE/FALSE…Site · nickprockBenchmarks & researchAuto-optimizing Jev: Half the Errors, 1/7 the CostKiln points its autoresearch loop at Jev for Mandarin pinyin disambiguation.GuideBenchmarks & researchAutoTrust JEV-27B-VLThe vision sibling: the same text-trained System 1 head on Qwen3.8-27B's image encoder, taking images zero-shot, ranked first of 20 vision decision…Site · AutoTrust AI LabBenchmarks & researchbev-decider 0.4BA 0.4B Jev-compatible decision model with measured order invariance: 960 random option shuffles moved no probability by more than 1e-5, and…Site · avbiswas
 Benchmarks & researchClassifier BenchHead-to-head benchmark of fast typed classifiers, TypeSafe Jev, OpenAI Decisions and Cloudflare Clef, against Claude models on a frozen, labeled…GitHubBenchmarks & researchDarwin-27B-ZTCFINAL-Bench's zero-token classifier: one forward pass plus a fitted temperature produce a full distribution over options, scoring 0.743 on the…Site · FINAL-BenchBenchmarks & researchDecider Chat Gemma-4-31BAn untrained readout: stock Gemma-4-31B weights plus a decider config that reads option letters at the answer slot, scored #2 of 70 on Decision Index…Site · Mapika
 Benchmarks & researchDecision Models ShowdownTwo runnable demo apps that send identical typed questions to OpenAI Decisions (gpt-6-luna) and TypeSafe Jev (jev-latest) in parallel: a support…GitHubBenchmarks & researchDeepSearcher Jev stopping experimentAgentic search evaluation inside Zilliz DeepSearcher: a standalone harness replaces the ChainOfRAG reflection call with one Jev Noul per round to…GitHubBenchmarks & researchDrex DLMNace.AI's 8B decision model on NVIDIA's Efficient-DLM diffusion backbone: a 256-dim pointer head scores every option in one pass, behind the same…Site · Nace.AIBenchmarks & researchGero-4BA 4B scorer rebuilt from Qwen3-4B into a branching cross-encoder: one branch per option, no position bias, up to 256 options, and calibrated…Site · vixhal-baraiyaBenchmarks & researchInside Halv's 57.1% Cost Reduction: SWE-rebench DataHalv reports a paired SWE-rebench comparison where its workflow, an Astra coordinator, a Luna investigation stage, and JEV selecting worker models…GuideBenchmarks & researchInterfaze LevInterfaze's 4B LoRA adapter over Qwen3.5-4B that speaks POST /v1/systemone: 0.807 held-out weighted accuracy and 0.061 ECE after calibration, with a…Site · Interfaze
 Benchmarks & researchJev against Claude Haiku 5.5 on 262 real decisionsJev got 204 right and Haiku 5.5 got 177.X post · Stanislav SorokinBenchmarks & researchJev Distill Corpus v3The 741,000-row distillation corpus behind AutoTrust's Jev students: choice, score, and noul rows with full target distributions across yuri and…Site · SargeDev
 Benchmarks & researchJev Eval — Shogo-nfrealmusicThird-party TypeScript check that compares Jev (typesafe-ai/jev) against openai/gpt-4o-mini and anthropic/claude-sonnet-4.5 under identical…GitHubBenchmarks & researchJev for Voice Agent Turn DetectionVeris tests Jev as a semantic turn-detection gate for one Pipecat voice agent from its VAmoS Pro Bench, with labels complete, short, and long.Guide
 Benchmarks & researchJev Regress BenchReproducible benchmark asking which approved agent answers changed meaning after a config edit: one Jev Choice (same, fact_differs, action_differs,…GitHub
 Benchmarks & researchJev TestSmall test harness and benchmark for Jev through OpenRouter's Decisions API.GitHubBenchmarks & researchJev-as-a-Judge for Agent EvalsLangChain's LangSmith team benchmarks Jev as an agent evaluator against GPT-5.6 Luna, Terra, and Claude Sonnet 4.6 on five captured weather-agent…GuideBenchmarks & researchJev-Driven SRE Diagnosis: What Worked and What FailedSREGym benchmarks a Jev-only diagnosis pipeline with no LLM in the loop: it programmatically collects Kubernetes evidence, then Jev picks the…Guide
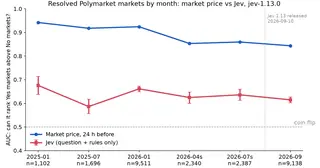 Benchmarks & researchjev-polymarket-testTests whether a Jev Noul ("this market resolves Yes") beats the Polymarket price on resolved markets, with blind vs priced variants and a…GitHub · truongxxxx
 Benchmarks & researchJevTalkExperiment that gets Jev to answer questions in plain English by spelling answers one choice at a time, drafting in parallel and picking the best…GitHub · Promptable-TechnologiesBenchmarks & researchJulia-1 Decision DemoA ZeroGPU demo of Julia 1: define a state and any set of choice, score, and noul questions and see per-option probabilities rendered as bars and raw…Site · Supersonic LabsBenchmarks & researchLaya Typed-DecisionsThe fine-tuned Laya checkpoint for four typed-decision workflows: 0.766 accuracy on 2,000 held-out decisions, above Jev 1.13.0's published 0.727 and…Site · Convai InnovationsBenchmarks & researchLiquid AI d1-3BLiquid AI's 3.12B decision model built on LFM2.5-VL: state plus typed questions in one forward pass with zero output tokens, 48.57 on Decision Index…Site · Liquid AI
 Benchmarks & researchMicrosoft Decision-1 against Jev at Contra600 decisions each. Jev got farther, and neither cleared Stage 1.X post · cola_runnerBenchmarks & researchMicrosoft-Decision-1 against Jev on a private eval60% F1 against 90% F1 on 3,000 private cases.X post · yessirBenchmarks & researchOpenDecider NanoA 400M-parameter Jev-compatible decision model with a browser build: 0.796 on typed decisions against Laya's 0.766, 17 ms per question on an L40S,…Site · Manjunath JanardhanBenchmarks & researchProcedural Typed Decisions572,000 procedurally generated decision problems where labels are computed exactly from rules in the state: 13 task families, 4–60 options, and…Site · tasksourceBenchmarks & researchPT-BR Typed Decisions BenchmarkA native Brazilian Portuguese typed-decisions benchmark: seven choice and noul tasks over legislative, legal, scientific, and fact-checking text,…Site · FelhenBenchmarks & researchS1MB LeaderboardThe System One Mosaic Benchmark leaderboard: about 100 decision models compared across 100+ specialized tasks, with results regenerated from a public…Site · hotchpotchBenchmarks & researchTasksource Jev Typed-Decisions2.5 million typed decisions recast from 670 sources: choice, score, and noul rows with per-row licenses, soft annotator targets, and Jev-audited mix…Site · tasksourceBenchmarks & researchTyped Decision LeaderboardAn independent 2,018-item answer-verifier benchmark: the same items and labels for every entrant, each run on its own maker's code, with Jev,…Site · mayafreeBenchmarks & researchTyped Decisions BenchmarkThe 400-case, 2,000-decision benchmark open models train and report against: four workflows, state plus typed questions, and gold distributions…Site · LocalLLaMA
 Benchmarks & researchcarve-jevOpen-source Jev-like model family with one-token Qwen3.8 decisions, TypeSafe API, one-command setup, and reproducible benchmarks.GitHub · ★ 11 · FuturixAI-and-Quantum-Works
 Benchmarks & researchJevOutCode and evaluation tools for JevOut: Natural Context Can Flip Decision Models.GitHub · ★ 2 · xzx34
 Benchmarks & researchmodele-decyzyjne-testSmall evaluation from the Institute of History of the Polish Academy of Sciences: 250 human-labelled fragments of the 19th-century Polish…GitHub · IHPAN
 Benchmarks & researchfinance-decision-evalsIndependent evaluation of TypeSafe Jev on ASC 606 revenue-recognition calls: whether a non-standard software contract clause needs revenue accounting…GitHub · vicwlauBenchmarks & researchGoogle's MediaPipe Decision Maker, tested in the browser75% on its own, against 92% for Jev.X post · Natzir
 Benchmarks & researchgutsyA 0.8B local decision model on an ordinary CPU.GitHub · ★ 89 · kouhxp
 Benchmarks & researchjev-playground (deepdave98)Weekly builds on Jev (TypeSafe AI), benchmarked honestly enough to publish.GitHub · ★ 31 · deepdave98
 Benchmarks & researchAwesome-jev-papersAwesome papers, benchmarks, and research resources for jev and related research.GitHub · ★ 15 · Oscar-dzy
 Benchmarks & researchsocial-risk-qwen-jevConcluded research project (Chinese, with English README) on multimodal risk moderation for Chinese social posts (LT-EDI Chinese misogyny memes):…GitHub · ★ 6 · TianJinWeiBoss520
 Benchmarks & researchjevectorDecision-vector profile retrieval with Clef and Jev, HNSW search, and BM25/BGE benchmark comparisons.GitHub · ★ 5 · lalalune
 Benchmarks & researchgutfeelUsability testing for MCP servers: a participant that doesn't deliberate — TypeSafe Jev by default — walks your tools on realistic, hint-free…GitHub · ★ 2 · huayaney-exeBenchmarks & researchhunch (rajkharvar)Browser-only playground for TypeSafe's Jev decision model.GitHub · ★ 1 · rajkharvar
 Benchmarks & research2048: Jev vs LayaExperiment where two System One decision models — hosted TypeSafe Jev and open-weight Laya (plus a LoRA fine-tune) — play 2048 on the same seeds…GitHub · Devikrishna545Benchmarks & researchvals.aiTies frontier models on claim verification, last of twelve on LegalBench.Site · Vals AIBenchmarks & researchkitsuno.aiKitsuno trains an open model to replace Jev in production.Site · Kitsuno
 Benchmarks & researchToolDiscoveryBenchBenchmark of how accurately and quickly a router picks the right MCP tool: the same golden questions run against real MCP tool catalogs (with seeded…GitHub · SarathChandraBellam
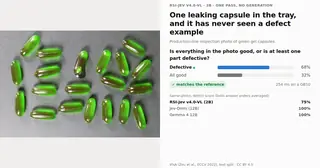 Benchmarks & researchRSI-JevDecision models trained by a self-improving loop of AI agents.GitHub · ★ 116 · Shanghua-Gao
 Benchmarks & researchTypeWrightDeclarative compiler: state/decisions → frozen typed Jev JSON program via DSPy/GEPA (alpha; no live accuracy claims yet).GitHub · ★ 7 · Jev-Engineering
 Benchmarks & researchdecidealotMake the call. Run local Laya, Von, CLM or hosted Jev for typed classification and scoring through one HTTP and MCP API, with resource-aware batches.GitHub · ★ 3 · psyb0t
 Benchmarks & researchjev-testStress-Testing Jev's Confidence.GitHub · ★ 3 · mity-prodgen
 Benchmarks & researchSoulsBenchDark Souls III realtime combat benchmark for decision models: TypeSafe Jev, OpenAI Decisions, Perplexity's decider and local Kev / Laya each fight…GitHub · ★ 3 · AWoLnik
 Benchmarks & researchtypesafe-evalFast, typed multi-dimensional document evaluation CLI powered by TypeSafe System One (Jev).GitHub · ★ 2 · s-0-a-r
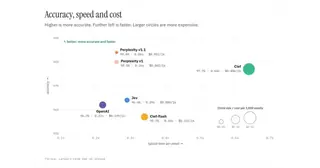 Benchmarks & research1,565 emails, six decision modelsPerplexity v1.1 came out best overall, OpenAI was the fastest.X post · Nikhil Mudholkar
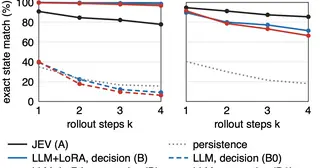 Benchmarks & researchA Decision Model as a World ModelCode, data, run logs and manuscript for a KIIS 2026 Fall Conference paper testing whether a frozen TypeSafe Jev decision model can serve as an LLM…GitHub · thddydgnl
 Benchmarks & researchAlbanian sentiment analysis with JevReproducible study classifying Albanian COVID-19 Facebook comments (AlbAna, three-annotator labels) with TypeSafe Jev and no training, re-running the…GitHub · uran-lajci
 Benchmarks & researchDecision-model referral on medical examsCode, recorded runs and manuscript for a preprint (Sangzin Ahn, 2026) comparing TypeSafe Jev, OpenAI Decisions and Cloudflare Clef on 435 KorMedMCQA…GitHub · mahlernim
 Benchmarks & researchDecisionBenchEvaluation harness and dashboard comparing TypeSafe Jev (via OpenRouter) with Claude Sonnet 5 on the same structured decision tasks — 100 real…GitHub · KizitoNaanma
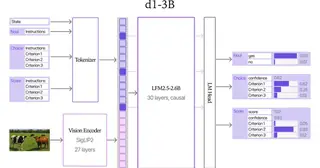 Benchmarks & researchLiquid d1-3BFirst among models under 10B on the Decision Index v0.2.1.X post · Liquid AI
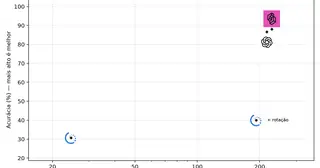 Benchmarks & researchopenai-decisions-vs-jev-vs-layaIndependent Portuguese-language benchmark of decision models — OpenAI Decisions API (gpt-6-luna), TypeSafe Jev (jev-1.13.0) and local Laya (with…GitHub · mateusfonsek
 Benchmarks & researchOpenRouter Decision Model RankingsSpend share and token share of decision models, by task type.X post · OpenRouter
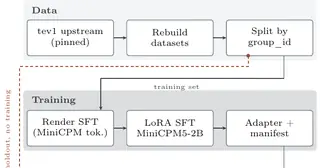 Benchmarks & researchReJevReproducible MiniCPM5-2B post-training for Jev-style single-letter Choice decisions, with sealed holdout evaluation.GitHub · ★ 20 · Joe-rq
 Benchmarks & researchTopicJevAn Efficient Low-Resource Bootstrap for Topic Model Refinement in Zero-Shot Settings.GitHub · ★ 9 · anatems1
 Benchmarks & researchsystem-one-parsersLab building a domain-free Universal Dependencies parser out of many small Jev questions — one Choice per word for part of speech, then head and…GitHub · ★ 3 · Engid
 Benchmarks & researchardanaRun System 1 decision models locally.GitHub · ★ 2 · ardana-ai
 Benchmarks & researchChessWithJevEvaluating Jev for chess decisions.GitHub · ★ 1 · iamvineeth23
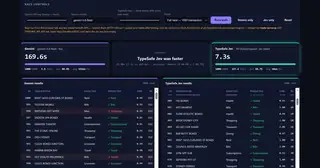 Benchmarks & researchLLM vs JevTeaching demo that races Gemini against TypeSafe Jev on the same 1,000 bank transactions into 12 categories, side by side, scored on speed and…GitHub · codergarten
 Benchmarks & researchMatilda JevMaincode's open 26B decision model, trained in Australia.X post · Marcel
 Benchmarks & researchOpenAI Decisions against Jev and ClefA head-to-head video on the day OpenAI's API opened.X post · Ryan Vogel
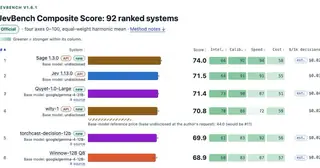 Benchmarks & researchSage by LevantoLabsA decision model launched in July that claims first place on JevBench.X post · Marco De Rossi
 Benchmarks & researchSystem-1 decision benchmarkCommon-ground benchmark of 50 System-1 decision-model configurations — Jev, Clef, Clef-flash, Kev, Nimble and Tev1 against embedding, reranker, NLI…GitHub · Sj0605-DataSci
 Benchmarks & researchWhere open source scores against JevA 74M-parameter GLiNER model beat Jev at Doom.X post · James Briggs
 Benchmarks & researchBud-Decision-EngineAn open-source LM Studio for decision models.GitHub · ★ 108 · BudEcosystem
 Benchmarks & researchWaterSheepAn open, Apache-2.0 decision model with a local server that accepts Jev's /v1/systemone requests, for people who want Jev-style typed answers without…GitHub · ★ 13 · SamratDuttaOfficial
 Benchmarks & researchlevOpen System One decision model (Qwen3.5-4B LoRA): one state, many typed Choice/Noul/Score answers in one forward pass over /v1/systemone—independent…GitHub · ★ 10 · Abhinavexists
 Benchmarks & researchOpenJevSwiftNative Swift implementation of OpenJev: Jev-compatible System One typed decisions (noul, choice, score) on Apple silicon.GitHub · ★ 10 · Algorythm-Canada
 Benchmarks & researchwhat-the-jevWhat can Jev actually do? Reproducible experiments and research reports exploring its capabilities and limits.GitHub · ★ 9 · keta1930
 Benchmarks & researchawesome-open-system-oneCurated list of the open System One ecosystem: open models, independent benchmarks, calibration and constrained-decoding tooling.GitHub · ★ 8 · rupeshpoojary9
 Benchmarks & researchjebadiahJebadiah, an open System One decision model: trainer, data builders, evals and every run record.GitHub · ★ 7 · getainode
 Benchmarks & researchzero-shot-ie-bench60 zero-shot information-extraction & classification systems (57 benchmarked) across 32 families — extractor encoders, zero-shot classifiers,…GitHub · ★ 7 · umstek
 Benchmarks & researchawesome-jev-securityCurated list of papers on the security, robustness, and safety of TypeSafe Jev / System One models.GitHub · ★ 6 · Sarim-MBZUAI
 Benchmarks & researchgutJudgment calls as one line of Python, built for TypeSafe AI's Jev and running on any small model: likely / classify / rate → YES, NO or UNSURE.GitHub · ★ 6 · Kungie
 Benchmarks & researchjevaltOpen Jev-API–compatible Choice/Score/Noul models (EN/TR/DE) for CPU (~4 GB RAM); independent of hosted Jev.GitHub · ★ 5 · mertkayacs
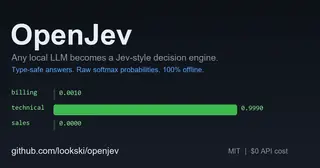 Benchmarks & researchopenjev (lookski)Local open decision engine: turn any small LLM into a Jev-shaped typed-decision API via masked-logit softmax—independent of hosted TypeSafe Jev.GitHub · ★ 5 · lookski
 Benchmarks & researchjev-bushJev Bush is a CPU-first probabilistic decision engine for bounded DiffusionGemma decisions.GitHub · ★ 5 · artalis-io
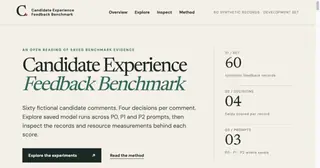 Benchmarks & researchcandidate-experience-benchmarkBenchmark comparing TypeSafe Jev vs LLMs on 60 synthetic candidate-experience reviews across four typed classification tasksGitHub · ★ 4 · adambkovacs
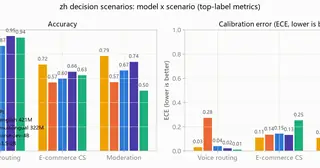 Benchmarks & researchzh-decision-benchChinese-language calibration benchmark for Jev-class System One decision models (dataset CC BY 4.0; code Apache-2.0), including Jev and NeoHorse armsGitHub · ★ 3 · CodyQin
 Benchmarks & researchsokudanJapanese System One decision model: typed answers and probabilities in one forward pass—no text generation.GitHub · ★ 3 · hiroki-abe-58
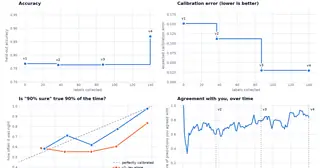 Benchmarks & researchJev-FlywheelJev plus a decision head that learns from feedback: can a loop name a bias we planted in our own dataset?GitHub · ★ 3 · AnthusAI
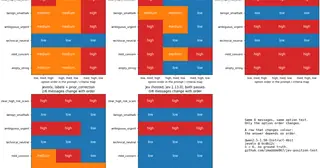 Benchmarks & researchjev-position-testReorder the enum options: a Jev clone changes its answer, Jev doesn't.GitHub · ★ 3 · imaddde867
 Benchmarks & researchjev-skills (laguagu)Practical agent skills and examples for building with Jev.GitHub · ★ 3 · laguagu
 Benchmarks & researchjev-spatialJev-Spatial is a System One spatial model inspired by Jev.GitHub · ★ 3 · Fr0zenCrane
 Benchmarks & researchpi-jev-todo-auditPi extension that audits rpiv-todo board drift every 10 agent loops using TypeSafe's jev model, injecting corrective nudges when the agent wanders…GitHub · ★ 3 · xz-dev
 Benchmarks & researchRazeOffensive-security agent built on Raze, a System One model in the Jev family — turns target state into typed, calibrated judgments (exploitability,…GitHub · ★ 3 · JoasASantos
 Benchmarks & researchwarped-sys1-labJev (TypeSafe System One) experiment lab: SvelteKit workbench and CLI.GitHub · ★ 3 · fini
 Benchmarks & researchJEValsPlayground for evaluating System One and JEV-compatible models with fidelity, semantic judging, and independent verification.GitHub · ★ 2 · duberblock
 Benchmarks & researchjevossProbe suite for any Jev-API decision model: accuracy, calibration, and adversarial recipes (Jev/Laya/etc.).GitHub · ★ 2 · mertkayacs
 Benchmarks & researchs1-tuiTerminal UI for System One typed decisions (noul/choice/score) over laya (local MLX) and TypeSafe Jev backends.GitHub · ★ 2 · tnaftali
 Benchmarks & researchdecision-model-auditReproducible field test of decision models (TypeSafe Jev, GLiNER2.5-Decide, Laya) against small LLMs and supervised baselines on fresh September 2026…GitHub · ★ 2 · oborchers
 Benchmarks & researchJEVJEV 调研报告:TypeSafe System One 决策模型与开源对标(含原始核实记录).GitHub · ★ 2 · Chorylee7
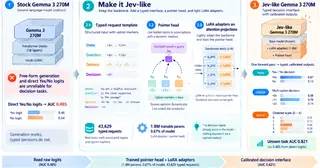 Benchmarks & researchjev-270mA System One decision interface on Gemma 3 270M: typed, calibrated decisions in one forward pass.GitHub · ★ 2 · deep-diver
 Benchmarks & researchJevESMOApoyo a la decision clinica oncologica: guias ESMO (43 tumores) + Jev System One, con explicabilidad y evaluacion.GitHub · ★ 2 · julianig72
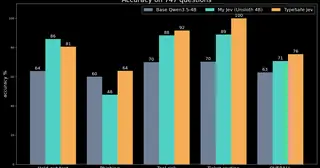 Benchmarks & researchmy-jevBuild your own Jev-like System One classifier: fine-tune Qwen3.5-4B with Unsloth on RunPod, serve with vLLM, benchmark vs TypeSafe Jev.GitHub · ★ 2 · PromptEngineer48
 Benchmarks & researchJevletFrom-scratch research reconstruction of a Jev-like System One decision model (typed Noul/Choice/Score → probabilities, no text generation) plus a…GitHub · ★ 1 · NAME0x0
 Benchmarks & researchaskjevEveryone asks what Jev is; I asked how it's doing, then a million other things.GitHub · ★ 1 · brian-w-zhang
 Benchmarks & researchdecguardReliability testing for probabilistic AI decisions in system-one-models.GitHub · ★ 1 · suffro
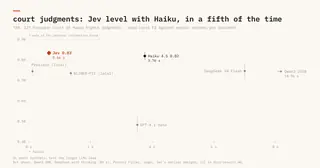 Benchmarks & researchjev-vs-piiHow good is Jev, a decision model, at finding personal information?GitHub · ★ 1 · AlanViollier
 Benchmarks & researchsmartvitaePlataforma de Adequação Curricular Factual e Alinhamento de Carreira com Zero Alucinação de IA.GitHub · ★ 1 · rafaelleaomedBenchmarks & researchJev in the Wild: A Data-Driven Analysis of the Jev…The first data-driven survey and analysis of Jev's application ecosystem, examining 2,170 public GitHub projects to document rapid early growth,…Guide
 Benchmarks & researchjev-guardbenchBenchmark harness asking whether a System One model (hosted TypeSafe Jev or self-hosted open-source Kev) can stand in for LLM-as-judge in agent…GitHub · dfranco-projectsBenchmarks & researchJev's bias analyzerAnswers this question with actual experimental data: Would JEV change its mind about you if your profile changed?Site
 Benchmarks & researchjev-zh-tw-evalTraditional Chinese (zh-TW) evaluation of Jev-compatible System One models (Plumb-4B via Ollama), including adversarial probes.GitHub · wuchengwei1996
 Benchmarks & researchWorkflowEvalsOfficial TypeSafe reproducibility harness for evals.typesafe.ai workflow benchmarks (invoice, customer service, agent traces, security incidents).GitHub · ★ 17 · typesafe-ai
 Benchmarks & researchBrierLocal calibrated choice/score/noul decisions in TypeSafe Jev API form, trained for Portuguese, on Apple Silicon MLX.GitHub · ★ 8 · Mangaba-ai
 Benchmarks & researchTev1 50 Use CasesFifty runnable tev1 decision-model examples through local Ollama, from ticket triage and guardrails to six playable games, with a live request viewer…GitHub · ★ 6 · PromptEngineer48
 Benchmarks & researchJev EvalsRubric-based eval harness that judges LLM and agent outputs with Jev through the Vercel AI Gateway, answering all rubrics for a case in one round…GitHub · ★ 3 · NicolasMontone
 Benchmarks & researchJev Tmmluplus EvalHarness that sits Jev for the 66-subject Traditional Chinese TMMLU+ suite, asking every item as one four-way A/B/C/D choice with calibration…GitHub · ★ 3 · lianghsun
 Benchmarks & researchJevNextLearning project rebuilding a Jev-style decision model on a frozen Qwen3-0.6B backbone with a rank-16 LoRA, served alongside text generation from one…GitHub · ★ 2 · DejaAI2
 Benchmarks & researchagent-workflow-typesafe-aiStandalone TypeSafe AI/Jev semantic-evidence adapter for bounded Agent-Workflow decisions, explicit uncertainty, compatibility evaluation, and…GitHub · ★ 1 · ngallodev-software
 Benchmarks & researchApple Silicon Systemone BenchmarkNative Apple Silicon harness comparing local decision models through one decision interface, running models serially and emitting an offline…GitHub · ★ 1 · Giamme
 Benchmarks & researchCan Jev BayesBayesian decision study probing Jev on stationary Bernoulli multi-armed bandits, testing whether posterior statistics, exploration instructions, and…GitHub · ★ 1 · TomRichner
 Benchmarks & researchDlm JevJev-style local decision engine on DiffusionGemma 26B-A4B that reads one label-token slot per question in a single decoder pass to return…GitHub · ★ 1 · seongyeon1
 Benchmarks & researchJev Reality CheckIndependent Chinese-language test harness probing Jev `jev-1.13.0` where vendor claims hold and break: program-computed ground truths, recorded…GitHub · ★ 1 · ruffood
 Benchmarks & researchJev SimWire-compatible Jev re-implementation reading typed decisions from an LLM's next-token logits, plus a reproducible JevBench-based comparison of that…GitHub · ★ 1 · dashbi1
 Benchmarks & researchjev-imdb-benchmarkBenchmark TypeSafe Jev on IMDB reviews (sentiment/spoilers/quality) with published accuracy, latency, and cost.GitHub · ★ 1 · rahulbansalc6414
 Benchmarks & researchJev-is-oddDeliberately overengineered TypeScript package that asks Jev whether an integer is odd, with ESM and CommonJS builds, typed answers, and token and…GitHub · ★ 1 · robipop22
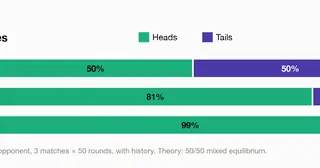 Benchmarks & researchJev_vs_Laya_decision_gamesHarness pitting Jev against Laya across six game-theory games with identical rules, plus a browser app to watch matches or play against the models…GitHub · ★ 1 · minanayernia
 Benchmarks & researchMagi System On JevEvangelion-inspired MAGI demo that runs a question past three independent Jev sages and decides by majority vote over calibrated probabilities, with…GitHub · ★ 1 · hide-G
 Benchmarks & researchMinicpm5 2B JevOpen-weight 2B single-pass System One decision model on MiniCPM5-2B that answers a shared-state dictionary of choice, noul, and score questions in…GitHub · ★ 1 · yuting-aiBenchmarks & researchJev Decision Index v0.3Stronger benchmarks, a private half, and vision.Site · apolinario
 Benchmarks & researchA playground pass from early accessTuring Post TV tests Jev from early access in the TypeSafe playground, starting from the constraint that it does not write essays or code.YouTube · Turing Post TV
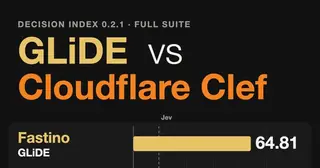 Benchmarks & researchGLiDE against Jev, Cloudflare and PerplexityA benchmark of the top decision models with one clear winner.X post · Sahibzada Allahyar
 Benchmarks & researchJev Access DayLearning scaffold teaching the System One pattern across triage, checkout, dunning, and PR review, with mock, LLM stand-in, and real Jev providers.GitHub · andreaserradev-gbj
 Benchmarks & researchjev-vs-clefHead-to-head stress comparison of TypeSafe Jev (via the Vercel AI Gateway) and Cloudflare Workers AI Clef (27B) / Clef-flash (9B) on synthetic,…GitHub · rmax-aiBenchmarks & researchLies, Damned Lies, and BenchmarksTypeSafe's 11 September 2026 essay against benchmaxxing: a public eval can select the model even when nobody trains on that test.Guide · TypeSafe AIBenchmarks & researchLocalLLaMA: Jev as a classifierThe r/LocalLLaMA thread arguing that Jev's constrained probabilities are ordinary zero-shot classification, and that the comparison should be other…Guide
 Benchmarks & researchSystem1 Fraud Interceptor DemoLocal demo that runs Jev and Gemini in parallel over synthetic transactions, comparing decision, latency, tokens, and audit record.GitHub · ordepas
 Benchmarks & researchTjevIndependent Qwen3.5 typed-decision stack in JAX with Pallas TPU kernels, LoRA tuning, per-type calibration, and MLX export.GitHub · tychota
 Benchmarks & researchOpenthai SystemoneOpen Thai plus English decision model that answers typed choice, score, and noul questions about a state in one forward pass.GitHub · ★ 68 · iapp-technologyBenchmarks & researchDecision Index (apolinario)Reproduce the Decision Index benchmark for typed decision engines (choice/noul) locally or as one Hugging Face Job.GitHub · ★ 49 · apolinario
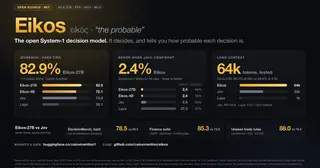 Benchmarks & researchEikosOpen MIT family of typed-decision models in 4B and 27B with GPU and Apple Silicon builds, answering structured questions in one forward pass with…GitHub · ★ 41 · caiovicentino
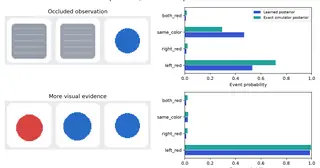 Benchmarks & researchOpenJev-VisionOpen research toolkit that encodes an image once and answers multiple typed choice, noul, and score questions from a shared distribution, plus a…GitHub · ★ 40 · IamBusy
 Benchmarks & researchMica-v0.1-4BSmall decision model that returns per-answer probabilities for yes/no, 2-255 choices, or 2-10 level scores in one prefill over the SystemOne format.GitHub · ★ 37 · akivet
 Benchmarks & researchPix GolpeSplit-screen demo pitting Rust plus Jev against Python plus DeepSeek on the same Portuguese scam messages, with fund tracing over a simulated graph…GitHub · ★ 33 · sandeco
 Benchmarks & researchOpen Medical JevJev-class medical judgments from frozen open models—no fine-tuning—with routing gates and published exam comparisons.GitHub · ★ 24 · FeiLiuEM
 Benchmarks & researchJevbotDiscord bot forcing a textless decision model to speak by repeatedly picking the next word through vocab tournaments, a completeness check, and reuse…GitHub · ★ 21 · lyramakesmusic
 Benchmarks & researchNemotron_JevSelf-hosted Decision Lab that asks typed choice, yes-no, and score questions through a browser explorer and a TypeSafe-shaped local API backed by a…GitHub · ★ 15 · pst2154
 Benchmarks & researchJEMMOpen-weight multimodal judgment engine served over HTTP with a Jev-style POST /v1/systemone endpoint, answering choice, noul, and score questions…GitHub · ★ 14 · ypcypc
 Benchmarks & researchJev DirectoryBrowsable directory pairing 50 runnable judge-model evals with exact prompts against more than a thousand community builds, each linked to its…GitHub · ★ 14 · everyai-com
 Benchmarks & researchSnapjudgeLocal Jev-compatible decision server for Macs that reads answer probabilities from Qwen next-token logits in one forward pass, with no text…GitHub · ★ 14 · Micha0827
 Benchmarks & researchBevLocal HTTP API that scores 2-255 candidate options per field with a redistributed ternary GGUF, returning typed Choice, Noul, and Score answers as…GitHub · ★ 12 · Reza2kn
 Benchmarks & researchZevalsTypeScript AI-agent testing library (OpenCX Labs) for end-to-end conversation evals, whose aiAssertion judge can be a JevClient — TypeSafe Jev via…GitHub · ★ 11 · opencx-labs
 Benchmarks & researchDiffusion Jev SglangAn independent typed-decision server built on Google's DiffusionGemma and SGLang: it reads image pixels as well as text, returns choice, noul and…GitHub · ★ 11 · Hangzhi
 Benchmarks & researchTyped DecisionsA research reproduction of the Jev question shape — Choice, Score and Noul answered in one forward pass — trained and measured side by side on…GitHub · ★ 10 · kotoba-lang
 Benchmarks & researchTryjevBrowser playground for trying Jev decisions: pick a preset scenario, edit state and typed noul, choice, or score questions, then read probabilities…GitHub · ★ 7 · sugarforever
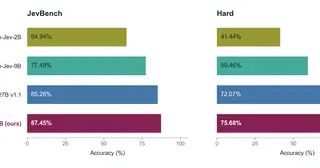 Benchmarks & researchCanopy-JevTree-based decision model on Qwen with shared context and isolated branches (independent System One–style research).GitHub · ★ 4 · Camellia86
 Benchmarks & researchMalkuthOpen-weight multilingual System One–style decision models (2B/4B, Korean focus): Choice, Noul, and Score over /v1/systemone via Kev—adjacent to…GitHub · ★ 3 · newfull5
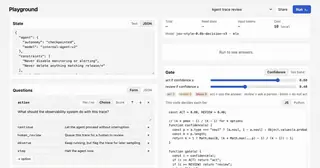 Benchmarks & researchJev-StyleSmall calibrated decision models you run locally, with a systemone-compatible server, agent skills, Claude Code guard, and MCP tools—weights on…GitHub · ★ 2 · lawrence3699
 Benchmarks & researchJev CarryforwardAn MCP server with two tools for agent memory: record writes facts into a per-project ledger as they happen, and recall scores each one against the…GitHub · ★ 2 · Dharundp6
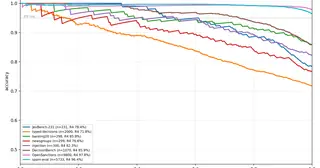 Benchmarks & researchTetraJevJev-class decisions on bounded decision problems from two frozen open-weight readers — four readings per item, fit-free fusion, agreement routing,…GitHub · ★ 1 · FeiLiuEM
 Benchmarks & researchjev-packsEvidence-gated registry of Jev question packs: curated questions, golden cases, pinned model versions, and reproducible offline benchmark results…GitHub · ★ 1 · dtduc-git
 Benchmarks & researchF1JEVRACE is a public archive of a racing experiment: ten driver prompts, thirty recorded races and six circuits, watchable in the browser with no API…GitHub · ★ 1 · MartinPuli
 Benchmarks & researchJev SkillbenchMeasures whether Jev can catch malicious agent skills on MalSkillBench, with a cascade arm that sends only the uncertain band to an LLM.GitHub · ★ 1 · MohibShaikh
 Benchmarks & researchPaper PackageAn evidence and reproduction package for a Jev decision study: the original fixed-split result on DBLP to ACM entity matching and SciFact relation…GitHub · ★ 1 · CompleteDotTechBenchmarks & researchClef and Clef-flashCloudflare's open-weight decision models, Jev API compatible.Site · Cloudflare
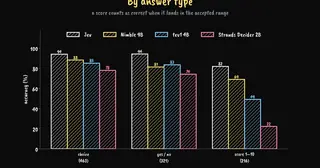 Benchmarks & researchcan-you-fool-jev1,000 English trick questions sent as identical /v1/systemone requests to Jev, Nimble 9B, tev1 4B and Strands Decider 2B, with the dataset, every…GitHub · huseyinbabalBenchmarks & researchClef on Hugging FaceThe Apache 2.0 weights for Cloudflare's Jev alternative.Site · Victor M
 Benchmarks & researchGround ZeroAn alpha Python library that uses Jev to grade model responses for hallucination, correctness and instruction following, returning Noul probabilities…GitHub · zavocc
 Benchmarks & researchJev Atari LabA research repository that asks how a teacher should rewrite the structured questions controlling an Atari player, publishing the negative results…GitHub · memorysaver
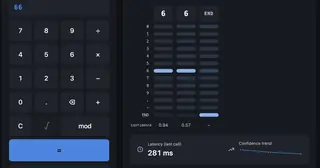 Benchmarks & researchJev CalculatorA calculator that lets Jev produce the digits: every step offers the same 13 options, a Cloudflare Worker forwards one System One choice request, and…GitHub · pc418
 Benchmarks & researchJev Calibration AuditAn unaffiliated, API-only audit of Jev calibration built on roughly 7,000 public HTTP calls, covering abstention, Korean, probabilistic coherence,…GitHub · jujumilk3
 Benchmarks & researchJev No EnemA public benchmark that scores Jev 1.13.0 on the Brazilian ENEM 2025 exam against open autoregressive baselines, reporting accuracy per subject area…GitHub · patryckalves
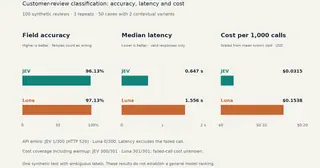 Benchmarks & researchJev Vs LunaA reproducible English benchmark running one review-classification rubric through jev-latest and gpt-5.6-luna, publishing per-field accuracy, macro…GitHub · mameli
 Benchmarks & researchLabsA sparse-checkout research workspace of independent lab write-ups, two of which cover Jev: one on API behaviour, input limits and multilingual…GitHub · kiarina
 Benchmarks & researchOpenWorkAn open Claude Cowork-style workspace whose eval testkit can call Jev as a typed verification judge on agent-produced artifacts.GitHub · ★ 24k · different-aiBenchmarks & researchLangWatchLangWatch Instant Evals ships a TypeSafe Jev classifier that batches Noul, Score, and Choice judgments on production traces in one POST per text.GitHub · ★ 4.9k · langwatch
 Benchmarks & researchCLM (Contrastive Language Models)Independent open System One model (CLM-8B: Qwen3-8B embeddings plus a small contrastive state/action head) served behind a TypeSafe-compatible POST…GitHub · ★ 3.0k · Contrastive-LM
 Benchmarks & researchJeff (firelex)Jeff: an open 0.8B "System 1" decision model (MIT code, Apache-2.0 weights on Hugging Face) that uses the same request format as Jev, with swappable…GitHub · ★ 1.5k · firelex
 Benchmarks & researchIntern-DecisionDecision models that answer several choice, score, and noul questions over a state with probabilities in one forward pass, with training, two…GitHub · ★ 745 · InternLM
 Benchmarks & researchJeeves (PostHog)PostHog’s open 9B Jev-like decision model with chain-of-thought before noul/choice/score answers and a Jev-compatible API.GitHub · ★ 422 · PostHog
 Benchmarks & researchOpen-Jev-27B-v1.1Typed probabilities from an open 27B model, with no generated JSON.GitHub · ★ 412 · Zefan Cai
 Benchmarks & researchimajevOpen Jev-style multimodal typed-decision models (photos+records+text → options with can't-tell).GitHub · ★ 380 · mohit67890
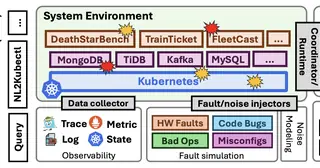 Benchmarks & researchSREGymPlatform and benchmark for AI agents that resolve production incidents in live Kubernetes environments (90 SRE problems, SREGym-Lite starter set),…GitHub · ★ 341 · SREGym
 Benchmarks & researchTasksourceStandardizes hundreds of public datasets into interchangeable multiple-choice, classification, and token-classification templates, and…GitHub · ★ 220 · sileod
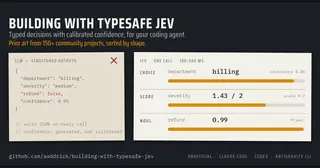 Benchmarks & researchbuilding-with-typesafe-jevUnofficial skill that teaches coding agents to build with TypeSafe AI's Jev: typed decisions, calibrated confidence, and prior art from 150+…GitHub · ★ 138 · aaddrick
 Benchmarks & researchWindTunnelWindTunnel is a benchmark harness for browser agents.GitHub · ★ 87 · nekuda-ai
 Benchmarks & researchDriveJevOpen System I autonomous-driving decision model (DriveJev-4B) scoring behaviours with probabilities in one forward pass; JevPilot closed-loop harness.GitHub · ★ 74 · benmagnifico
 Benchmarks & researchJames LibraryR.A.I.N. Lab is a local-first research environment.GitHub · ★ 56 · topherchris420
 Benchmarks & researchclef-webcamRuns Cloudflare's open-weight clef-flash decision model locally on an Apple Silicon Mac and turns live webcam frames into typed decisions (noul /…GitHub · ★ 35 · lucataco
 Benchmarks & researchJevBench (metamorphic)Metamorphic coherence testing for typed probabilistic decision models: 50 probability/choice laws without gold labels.GitHub · ★ 11 · JevBenchBenchmarks & researchenigma-jevSoftware Enigma/Bombe pipeline where TypeSafe Jev ranks cribs and judges whether a trial decryption is German—Bletchley Park’s human analyst steps as…Site · agodoy21Benchmarks & researchJev is the fish at the poker tableAn independent poker eval against TexasSolver: Jev matches solver top actions on easy spots but shoves the nuts into traps and needs explicit…Guide · backnotpropBenchmarks & researchOpenAI Answers TypeSafe's Jev with a Decision API Built…The Hacker News thread for The New Stack's write-up on OpenAI's Luna-based Decisions API and how it compares to TypeSafe's Jev launch.GuideBenchmarks & researchTypeSafe's Jev Can't See. I Made It Guess What I Drew…The Hacker News thread for Bartosz Mikulski's 400-drawing Jev versus Sonnet evaluation on SVG text.Guide · myszonBenchmarks & researchTypesafe's Jev is the fish at the poker tableThe Hacker News thread for backnotprop's TexasSolver poker evaluation of Jev action choices, trap spots, and decomposed question shapes.Guide
 Benchmarks & researchJev Harness LabEvaluation scripts, MCP tools, and a skill router built to measure where jev-1.13.0 fits in agent harnesses, with raw results under eval/.GitHub · ★ 3 · Aitejiu
 Benchmarks & researchdoppPoint Jev-shaped decision calls at one URL, keep every request, train a small model you own, run hosted/offline/browser—independent path.GitHub · ★ 2 · doppsh
 Benchmarks & researchv1-decisions-vllmProposed vLLM /v1/decisions typed-decision endpoint (Jev-compatible /v1/systemone projection) with pluggable logit/encoder/canvas…GitHub · ★ 1 · Timiku
 Benchmarks & researchDoes an open-weight decision model beat a hosted one?ASTGL compares local Laya with hosted Jev on typed decisions.Guide · James CruceBenchmarks & researchI built non-autoregressive decision models with RL a year agoA long thread on launch language, whether constrained routing is novel, and links to open Jev-like work including OpenDecision.GuideBenchmarks & researchJev and System One Models: Calibration Beats AccuracyThread on Kartik Pansuriya's essay arguing calibrated probabilities matter more than headline accuracy for production classifiers.Guide · pansuriyakartikBenchmarks & researchJev vs Kev on OpperOpper hosts Kev 4B and typesafe/jev-latest on the same /v1/systemone compat route and compares accuracy, tokens, and latency on 362 post-release…GuideBenchmarks & researchJev vs Kev tested side by sideThe Hacker News thread for Opper's hosted comparison of typesafe/jev-latest and opper/kev-4b on the same wire format.Guide · felix089
 Benchmarks & researchPost-train your own judge on your agent's tracesA 4B, 8B or 27B judge that beats Jev on human agreement.X post · laxman
 Benchmarks & researchSales pipeline revival (Jev vs Gemini)Open benchmark: TypeSafe Jev vs Gemini triage on 203 dead sales-deal email threads with published metrics (Salesgear companion).GitHub · developer943
 Benchmarks & researchThis AI Can't Write a Single Word. That's the Point.Heroic steps on typed decisions with confidence scores, parallel output speed, the Doom demo, and citations to TypeSafe, The Register, and Every.to.YouTube · Heroic steps
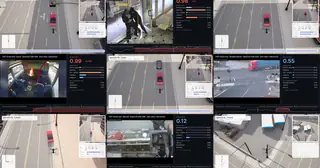 Benchmarks & researchvidjevSystem One–style decisions on live video: CARLA drone following and zero-shot CCTV anomaly detection with open vision-language models (and a djev…GitHub · numinousmusesBenchmarks & researchWe tested Jev on 100 real agent tool callsHacker News link to Archestra's write-up comparing Jev with a constant benign baseline on production Claude Code tool calls.Guide · arseny_infoBenchmarks & researchStrands DeciderRun a small fast System One–style decision model for agentic option/score/yes-no workflows (independent of hosted Jev).GitHub · ★ 611 · strands-labs
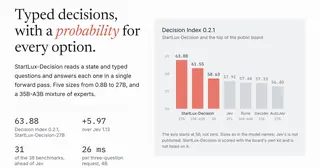 Benchmarks & researchStartLux-DecisionIndependent open typed decision models (0.8B to 35B-A3B, text and images) served on the TypeSafe /v1/systemone request format, with inference code,…GitHub · ★ 397 · StartLuxLabs
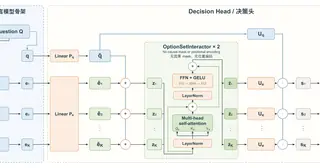 Benchmarks & researchOpenJev (ejhshen)OpenJev-4B open reproduction of Jev-style open-vocabulary probabilistic decisions (not TypeSafe-hosted; distinct from lookski/openjev).GitHub · ★ 21 · ejhshen
 Benchmarks & researchcodegraph-jevResearch log: can a code graph plus TypeSafe Jev match a coding agent at finding and ordering functions?GitHub · snemesh
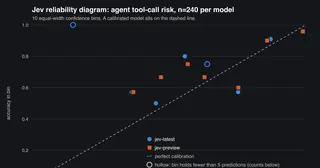 Benchmarks & researchjev-calibrationReliability diagram and ECE for TypeSafe Jev on 240 hand-labelled agent tool calls (labels + scripts published).GitHub · themsquared
 Benchmarks & researchJev-LiteOpen System One–style FastAPI decision engine (Qwen backbone) inspired by TypeSafe Jev; independent of hosted Jev.GitHub · Atulmishra22
 Benchmarks & researchjevosDecisions on a laptop CPU in 28 to 130 ms, behind Jev's API.GitHub · ★ 1.3k · Federico Elia
 Benchmarks & researchChinese-JevTraining/eval pipeline for Chinese-language System One–style typed decisions (CJ-Bench/CJ-Dataset); pretrained weights not included yet (independent…GitHub · ★ 15 · gulucaptain
 Benchmarks & researchJev calibration studyA sentiment study of whether Jev's stated confidence matches accuracy, comparing raw scores with Platt scaling and isotonic regression.GitHub · ★ 3 · AnthusAI
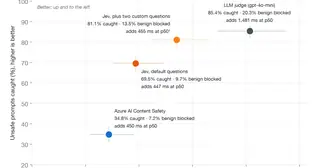 Benchmarks & researchjev-guardrail-benchmarkBenchmark of TypeSafe Jev content-safety guardrails in WSO2 AI Gateway vs Azure Content Safety and an LLM judge.GitHub · ★ 1 · randilt
 Benchmarks & researchFour synthetic ticket testsAI Test Bench runs four tests on synthetic support tickets in the official TypeSafe playground and states what that small set does not prove.YouTube · AI Test Bench AIBenchmarks & researchGLM-5.3-Flash as a decision modelPrivatemode's write-up of typed decisions from GLM-5.3-Flash in one forward pass, with latency, cost, and accuracy set next to Jev and Laya.Guide · Johannes Hötter
 Benchmarks & researchJev by TypeSafe AI, a System-1 decision modelCampusX on Jev as a classifier over schema-constrained choices, with a live benchmark and an e-commerce review demo.YouTube · CampusXBenchmarks & researchJev Calibration gameSixteen true-or-false statements you answer, then Jev answers with a Noul probability.SiteBenchmarks & researchJev can't be calibrated — news.ycombinator.comThe Hacker News thread on Alex Molas's calibration argument, including a commenter who reran the fair-coin and fair-die prompts.Guide · alexmolas
 Benchmarks & researchJev explained, with a live demoKodeKloud on why a System One model returns calibrated probabilities, then a Papers, Please-style queue where Jev is compared with GPT-5.5 and…YouTube · KodeKloudBenchmarks & researchJev hands-on against Sonnet 5Five self-funded experiments on jev-1.13.0 from a Mac mini, comparing direct HTTP with claude-sonnet-5 after an earlier test mistook CLI startup for…Guide · zhuermuBenchmarks & researchJev on 100 real agent tool callsArchestra labels 100 production Claude Code tool calls and compares Jev with a constant benign baseline, Sonnet 5, Laya, and several open decoders.Guide · Arseny KravchenkoBenchmarks & researchJev on 770 AITA postsThe Hacker News thread for the Am I the Asshole comparison, including a moderator note about generated text.Guide · dchristopoulosBenchmarks & researchJev vs Claude Opus 5 on Banking77OpenRouter's Banking77 run: 3,080 support utterances, 77 intents, Jev 1.13 against Claude Opus 5 on the same one-line criteria, with latency, cost,…Guide · Kenny Rogers
 Benchmarks & researchJev vs LayaUnder the Hood AI compares TypeSafe's closed decision model with Laya, the open model Convai released that can run on a laptop.YouTube · Under the Hood AI
 Benchmarks & researchjev-playgroundOpenRouter workbench for TypeSafe Jev: typed noul/choice/score questions with calibrated probabilities, latency/tokens/cost metrics, and Postman/cURL…GitHub · frederico-kluserBenchmarks & researchJevBench on Hacker NewsThe Show HN thread for a public benchmark of typed decision models, including a comment on the launch terms that discouraged benchmarks.Guide · florianstandharBenchmarks & researchJevPlay — jevplay.vercel.appA browser question builder for Choice, Score, and Noul.SiteBenchmarks & researchModerating a site with JevTom Nick's write-up before jevdit.com: irony detection on 100 German soccer tweets, with Jev 1.13.0 next to Opus, Astra, and Laya.Guide · Tom NickBenchmarks & researchOpenAI is well positioned to fast-follow JevThe Hacker News thread on John Berryman's argument that OpenAI could copy the decision-model shape and fold it into existing agents.Guide · JohnBerryman
 Benchmarks & researchopenjevxOpen-weight Jev-compatible System One decision server for jevx—local /v1/systemone from a Laya fine-tune.GitHub · muthuishere
 Benchmarks & researchReflex-1Reflex-1: a 4B open decision model for frontier-LLM accuracy at Jev-like speed (instant classification + latent reasoning).GitHub · matu79goBenchmarks & researchTurning GLM-5.3-Flash into a Jev-like modelThe Hacker News thread on Privatemode's GLM-5.3-Flash write-up, focused on whether a base model plus a classifier head can match Jev.Guide · flxflx
 Benchmarks & researchTypeSafe Jev fact-checkPrism Labs checks the launch demos against TypeSafe's own footnotes: what they keep from the 70 ms claim, and what they drop from the speed multiples.YouTube · Prism LabsBenchmarks & researchWhat Jev can do inside an agent harnessA black-box pass over ten public datasets with jev-1.13.0: injection detection, reranking, intent, tool routing, and three tasks the author says do…Guide · AitejiuBenchmarks & researchWill OpenAI eat Jev's lunch?John Berryman's argument that OpenAI already uses its models as implicit classifiers and could ship a general one inside agents, if it can match the…Guide · John Berryman
 Benchmarks & researchOpenDeciderOpen System One decision models (typed choice/score/yes-no) with calibrated probabilities; optional Jev-compatible /v1/systemone server—independent…GitHub · ★ 34 · manjunathshiva
 Benchmarks & researchpolyjevTyped, calibrated decisions from any LLM with a drop-in Jev-compatible API server.GitHub · ★ 2 · PraveenAShukla
 Benchmarks & researchJev-OmniA decision classifier for text, images, audio and video.Site · akhilaaa3Benchmarks & researchJev-Style 0.8B Decision v3Jev-style decisions on a laptop, 0.53 GB in 4-bit.Site · chaoliangUNSWBenchmarks & researchJulia 1A 144.3M-parameter decision model that edges Jev on typed decisions.Site · Supersonic LabsBenchmarks & researchautotrust/JEV-9BAn open student of Jev 1.13 with System 1 and System 2 in one set of weights.Site · AutoTrustBenchmarks & researchdecider-2bAn open reproduction of the System One model class on Qwen3.5-2B.Site · MapikaBenchmarks & researchJeff 1An open typed-decision model with a guide to training your own.Site · Gestalt Labs
 Benchmarks & researchjev (taifoon-io)Grade an AI agent job with TypeSafe Jev: fact checks in code, four closed questions, receipt with probabilities, optional on-chain records…GitHub · taifoon-ioBenchmarks & researchLaya VisionTyped decisions about an image plus text, in one forward pass.Site · r33drichardsBenchmarks & researchOpen-Jev-9BA LoRA adapter and decision head for Qwen3.5-9B.Site · Zefan CaiBenchmarks & researchOpenThai-SystemOneAn open Thai and English System One decision model.Site · iApp TechnologyBenchmarks & researchSystem One scorerQwen3.5-4B with a scoring head, type-safe by construction.Site · pngwn
 Benchmarks & researchhere-we-go-jevLocal playground and test bench for Jev System One with mock and LLM baseline backends.GitHub · ★ 1 · creativoma
 Benchmarks & researchJev Foundry JudgeDrop-in Azure AI Foundry agent evaluators powered by TypeSafe Jev, plus a BYOK demo app and model-router bench.GitHub · ★ 1 · nguyennhianhtri
 Benchmarks & researchjev-browsecompResearch harness comparing cheap TypeSafe Jev typed decisions (Choice/Noul act|review|abstain over stable doc ids) to full-LLM and Recursive Language…GitHub · jjd-lab
 Benchmarks & researchjev-ticket-triageReproducible support-ticket triage eval: TypeSafe Jev vs Together.ai LLMs on accuracy/cost/latency/confidence (WIP).GitHub · beese54
 Benchmarks & researchtev1 (Together)Open-weight Jev-inspired decision model (Qwen3.5-4B fine-tune) with training recipe and published results on Together.GitHub · ★ 141 · togethercomputer
 Benchmarks & research50 financial jobs, one modelThe Fintech Builder runs Jev on fifty financial jobs and shows where it works and where it does not.YouTube · youtube.com/@TheFintechBuild
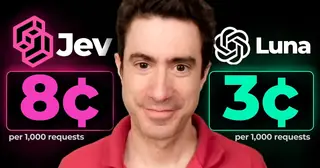 Benchmarks & researchIs Jev really better, faster and cheaper?Edward Donner puts Jev to the test against Luna.YouTube · youtube.com/@EdwardDonner
 Benchmarks & researchJev 1.13.0 against Hopper on Benchmark HeavenHopper wins three columns, Jev keeps Intelligence.Site · Benchmark Heaven
 Benchmarks & research"JEV-as-a-Judge: Accept When Confident, Escalate When…"JEV-as-a-Judge: Accept When Confident, Escalate When Unsure" This paper shows you can just use JEV for every evaluation instead of expensive LLM.X post · askalphaxiv
 Benchmarks & researchConvex Decision EvalsLeaderboard that puts Jev and 14 LLMs through 108 four-option multiple-choice questions about the Convex backend platform, comparing accuracy,…GitHub · ★ 129 · get-convex
 Benchmarks & researchValenTrain a Jev-like multimodal model yourself.GitHub · ★ 116 · Liuziyu77
 Benchmarks & researchCygnet recipeIndependent recipe that answers Jev-format typed decisions (choice, noul, score) with frozen Gemma-4-12B-it on unmodified vLLM via a one-token…GitHub · ★ 34 · blockbrain-ai
 Benchmarks & researchollayaOllama for decision models: pull one by name and serve it locally.GitHub · ★ 23 · ollaya-dev
 Benchmarks & researchjev-agent-design-with-topk-logits-choicesResearch design for a Jev-native agent system: tool integration, speculative parameter proposals, external helper logits Top-k proposals with…GitHub · ★ 8 · 6Mikao9
 Benchmarks & researchjev-dimabsaTypeSafe Jev baseline for DimABSA (SemEval-2026 Task 3) subtask 1: zero-shot and 3-shot valence-arousal regression.GitHub · ★ 7 · ZhangYiqun018
 Benchmarks & researchjev-benchmarkingCode for the arXiv paper by Deußer, Sparrenberg and Sifa (arXiv:2609.37647, 2026) benchmarking TypeSafe Jev (pinned jev-1.13.0) zero-shot on 37…GitHub · ★ 6 · AppliedMachineLearning-Lab
 Benchmarks & researchreflexbenchReflexBench — open benchmark and evaluation harness for System One models and typed decision engines.GitHub · ★ 5 · brida-ai
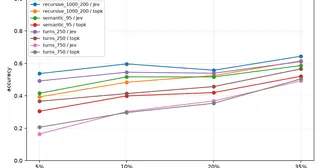 Benchmarks & researchjevtrimBenchmark: TypeSafe Jev as a context-relevance judge vs retrieval/summarization on LoCoMo, with matched token budgets and reproducible reports.GitHub · ★ 5 · pdrpinto
 Benchmarks & researchJev Does Not Play DiceIndependent calibration evaluation of Jev on fair random draws with known probabilities and synthetic forecast documents, with recorded outputs and…GitHub · ★ 4 · KantaHayashiAI
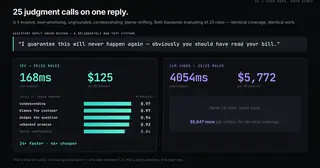 Benchmarks & researchjev-guardrailsResearch/eval repo that runs the same mock carrier support agent and 25 behavioural guardrail rules behind two backends—chat-model JSON judge vs…GitHub · ★ 3 · deepansh-saxena
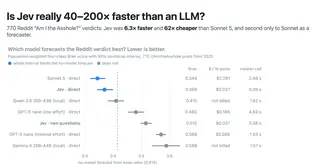 Benchmarks & researchjev-aitaBenchmark of TypeSafe's Jev against Sonnet 5, GPT-5 nano and local LLMs on 770 Reddit AITA verdicts: Brier scores, latency and cost.GitHub · ★ 3 · dchristopoulos
 Benchmarks & researchtypesafe-jev-calibrate-for-code-reviewAbout calibrating Jev for code reviews.GitHub · ★ 3 · Selmar
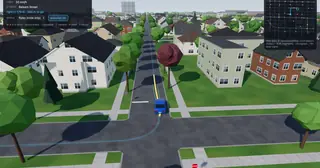 Benchmarks & researchjev_fsdBrowser driving simulator on real OpenStreetMap streets where TypeSafe Jev makes every maneuver choice, with a decision inspector and benchmarkGitHub · ★ 2 · BrendanH18
 Benchmarks & researchjev-dllmShared Yes/No decision adaptation with diffusion language models.GitHub · ★ 2 · zhouzihao11
 Benchmarks & researchJev-Research-IndexJev Research Index is a bilingual catalogue of papers, software projects, interviews, public analyses, demonstrations, and social-media material…GitHub · ★ 2 · AgenticAPP-Web
 Benchmarks & researchjev-reviewsTypeSafe AI - Jev - first look and experiment with its API + Google reviews experiments.GitHub · ★ 2 · halfspin-qc
 Benchmarks & researchopen_system_oneCreating system one model just like jev.GitHub · ★ 2 · Readyaddy
 Benchmarks & researchopenpave-jevPAVE skill for non-autoregressive decision models (Jev / Laya / TypeSafe): typed Choice, Score and Noul answers with calibrated probabilities.GitHub · ★ 2 · cnrai
 Benchmarks & researchLetJevDecideAsk a yes or no question. Let Jev, or a fair coin, decide.GitHub · ★ 1 · choxos
 Benchmarks & researchMEDJEVIndependent JEV-inspired System One-style typed decision research for clinical evidence, biomedical NLP, calibrated probabilities, and sleep signals.GitHub · ★ 1 · PAI-CUHK
 Benchmarks & researchsnbt-jev-benchJev on Indonesia's SNBT 2025 university entrance exam, whose papers are never released: 159 questions reconstructed from memory by volunteers, 156 of…GitHub · ★ 1 · misaalya
 Benchmarks & researchjev (zeke)Research notes and an interactive Cloudflare Worker demo for Jev, TypeSafe AI's structured decision model.GitHub · ★ 1 · zeke
 Benchmarks & researchjev-robotics-evalEvaluation harness for robot control with a JEV-compatible decision service on MetaWorld and RoboTwin tasks (text and vision modes, privilege levels,…GitHub · ★ 1 · lose4578
 Benchmarks & researchJevometryInformation-geometric toolkit for System One (Jev/Jevlike) decision probabilities—Fisher sensitivity over declared models.GitHub · ★ 1 · Kunyanli230
 Benchmarks & researchA faster, cheaper path for business modelsJev as an alternative for business logic.X post · MilkMendyBenchmarks & researchA local open-source version of JevRun a Jev-like decision model locally.X post · coccoinomane
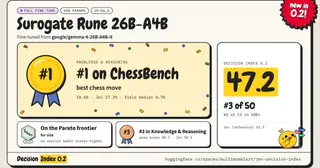 Benchmarks & researchA number two open-weight Jev-like modelAdded to the Decision Index, strongest for its size.X post · apolinario (poli)
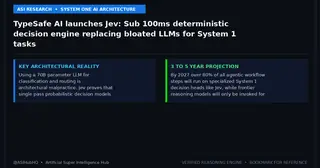 Benchmarks & researchA sub-100 ms decision engineHow the launch was described.X post · ASIHubHQ
 Benchmarks & researchAn LLM distilling JevTypeSafe notes an LLM distilling Jev.X post · TypeSafe AI
 Benchmarks & researchassayLocal open take on System One/Jev: typed answers with calibrated confidence from a small laptop model (stdlib Python).GitHub · patkusch
 Benchmarks & researchBounded choices, not proseJev returns a choice from the options it was given.X post · GeethanTech
 Benchmarks & researchCLM-8B claims to be faster than JevAn open model that its release claims is up to 9x faster.X post · aiasssistantstoreBenchmarks & researchCLM-8B, a new Jev competitorAn 8B decision model positioned against Jev.X post · plotarmordev
 Benchmarks & researchJev and Laya on a medical diagnostic testSixteen of sixteen against thirteen, on authored notes.X post · OpenMed
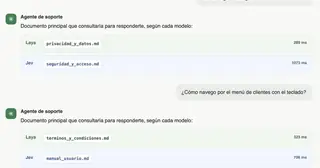 Benchmarks & researchJev and Laya on security queriesTwo decision models make different calls on the same security queries.X post · edwinfmesa
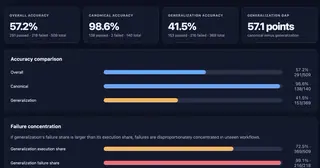 Benchmarks & researchJev for next best actionTesting Jev’s accuracy on predicting the next action.X post · dsmiley411
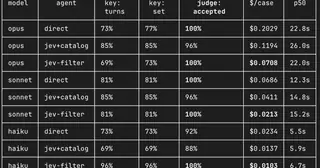 Benchmarks & researchJev in tool filtration testsPraised for filtering tools.X post · eboppu
 Benchmarks & researchJev vs. Sol, on categorisationA text categorisation showdown.X post · Jasonalco
 Benchmarks & researchjev-security-prioritizationReproducible experiment: TypeSafe Jev prioritizes SCA/SAST findings using richer context than severity scores, compared to severity-only and points…GitHub · san3ncrypt3d
 Benchmarks & researchLocal Laya beats JevA local decision model coming out ahead.X post · NeuralFrameLabs
 Benchmarks & researchPredicting queries before submissionA community test with Jev and Laya.X post · edwinfmesa
 Benchmarks & researchRYOTIDERoll Your Own Typed Inference Decision Engine: Jev-style typed decisions from a single forward pass of a local LLM (MLX or PyTorch), measured on…GitHub · csabag
 Benchmarks & researchSeparating signal from noise with Jev and OpusA pattern can still be noise, so ask what would change your mind.X post · DainBenchmarks & researchThe System One paradoxOn System One models and where Jev goes next.X post · __tuan____
 Benchmarks & researchTrying to beat Jev on a DGX SparkAn open System One model, with the data already collected.X post · Cuth
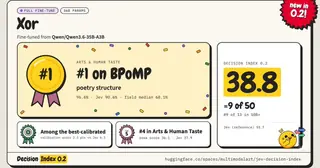 Benchmarks & researchxor joins the Jev Decision Index 0.2A new open-weight entry, eighth on text alone.X post · apolinario (poli)
 Benchmarks & researchjevk5An open-weight alternative to Jev, Apache-2.0.GitHub · ★ 105 · allebee
 Benchmarks & researchJevAnyOpen infrastructure for training, evaluating, and deploying System 1 decision models (independent of hosted TypeSafe Jev).GitHub · ★ 79 · SimpleJev
 Benchmarks & researchJev_StarA Jev and System One related repository.GitHub · ★ 37 · sc2musa
 Benchmarks & researchJevAnyCalibration-aware reinforcement learning for decision systems.GitHub · ★ 15 · weitianxin
 Benchmarks & researchtinyjevOffline ~0.6B System One–compatible decision model (Choice/Noul/Score with calibrated probabilities) on MLX or PyTorch—independent of hosted TypeSafe…GitHub · ★ 13 · ankit-aglawe
 Benchmarks & researchKevAn open-source System One engine with calibrated probabilities.GitHub · ★ 11 · arjun988
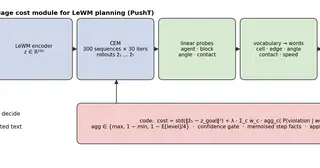 Benchmarks & researchlejudge-jev-jepaNatural-language constraints for JEPA planning, judged by a decision model.GitHub · ★ 9 · AbdelStark
 Benchmarks & researchawesome-jev-robustnessTests, calibration audits and failure-mode studies of Jev.GitHub · ★ 5 · Yifan-Lan
 Benchmarks & researchtypesafe-pocProva de Conceito do Jev, modelo da typesafe.ai.GitHub · ★ 5 · eminetto
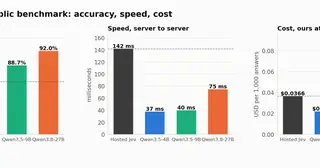 Benchmarks & researchBeating Jev with open modelsAn attempt to beat Jev’s accuracy, speed and cost with open models.GitHub · ★ 5 · rob313
 Benchmarks & researchawesome-jev-surveyAn evidence survey of Jev and Jev-like typed decision models.GitHub · ★ 4 · Eurekaleo
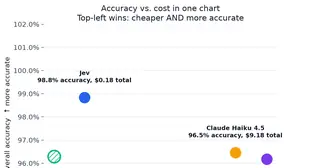 Benchmarks & researchjev-benchmark (YidiDev)Rubric-Based Zero-Shot Classification Benchmark: Jev vs Claude Haiku 4.5 vs OpenJev on rubric-conditioned classification, chained decision execution,…GitHub · ★ 3 · YidiDev
 Benchmarks & researchjev-deepresearchDeep research crawl where Jev (a System One model) makes every per-page decision and an LLM only plans and writes.GitHub · ★ 2 · tashfeenahmed
 Benchmarks & researchjev-x-kitOffline $0 decision layer for coding agents: Choice/Score/Noul primitives, BELKI confidence gatekeeper, ultra-planning, red-teaming, research and…GitHub · ★ 2 · Kadihx
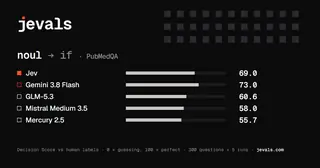 Benchmarks & researchjevals-dataIndependent benchmark data for TypeSafe's Jev (System One model) vs LLMs: accuracy, calibration, cost.GitHub · ★ 2 · Jevals
 Benchmarks & researchjevalyzerGrade the agent sessions already on your disk.GitHub · ★ 2 · killerz3
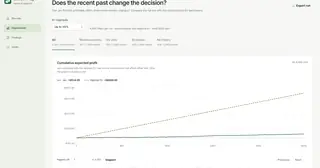 Benchmarks & researchcan-jev-playCan Jev infer whether a bet is worthwhile from its payout table, and do recent wins or losses sway that choice.GitHub · ★ 1 · carlaiau
 Benchmarks & researchrerank-bench-jevProduction reranker benchmark: TypeSafe Jev vs Qwen3-Reranker-0.6B on BEIR SciFact and NFCorpus — nDCG@10, cost/query and p50/p95 latency.GitHub · ★ 1 · denser-org
 Benchmarks & researchyc-jev-benchCan Jev replace an LLM reranker?GitHub · ★ 1 · PPRAMANIK62
 Benchmarks & researchsystem-one (mpuig)An open-source System One decision model — Kahneman's term for the fast, automatic judgment faculty.GitHub · ★ 1 · mpuig
 Benchmarks & researchA Jev-style local model for imagesTyped decisions, but for image inputs.X post · edplese
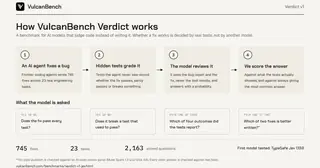 Benchmarks & researchAn eval suite for System One modelsBuilding the tests Jev-like models need.X post · morganlinton
 Benchmarks & researchDecision LabLocal visual System One playground for building decisions, comparing Jev, OpenJEV, and Laya, and exploring what-if evidence changes.GitHub · Amine-LG
 Benchmarks & researchDecisive judgment agents that don’t chatJev against Laya.X post · thelazyyogii
 Benchmarks & researchJev against Llama and DeepSeek235 ms median latency and 82% accuracy on the same labelled inputs.X post · RamV2003
 Benchmarks & researchJev catches the Opus 5.5 effort dropThe default effort moved from high to medium, and agents without settings lost reasoning.X post · 0xKiyoro
 Benchmarks & researchJev on a movie recommenderTesting Jev on recommendations.X post · utkarshgsuv
 Benchmarks & researchJev on Cloud RunAbout 47 s cold start and about 117 ms end to end on a cloud GPU.X post · _vmlops
 Benchmarks & researchJev vs. Laya-MLXA head-to-head comparison.X post · irSodeh
 Benchmarks & researchJevBenchA reproducible benchmark for typed decision models.Site · florianstandhar
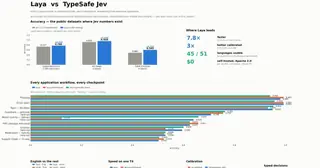 Benchmarks & researchLaya compared to JevAn open-source model next to the official one.X post · i_darshanjain
 Benchmarks & researchLaya on a 12-year-old laptop CPUSub-second decisions on an i5-5200U with no GPU.X post · Farhan60291312
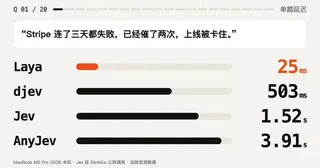 Benchmarks & researchLaya, 50× faster, on open alternativesA benchmark of the open-source Jev alternatives.X post · wquguru
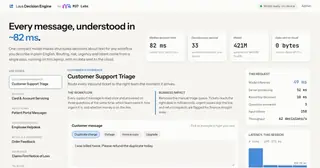 Benchmarks & researchLaya-MLX, taken apartA repo to understand an encoder-only decision architecture.X post · Zorawar Purohit
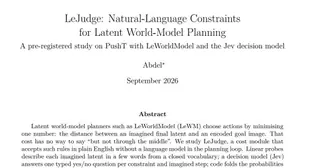 Benchmarks & researchLeJudge: JEPA × JevA JEPA world-model planner with Jev as the judge.X post · AbdelStarkBenchmarks & researchLocal Laya against cloud Jev, on latencyAbout 45 ms deciding locally against about 300 ms in the cloud.X post · Oluwaphilemon1
 Benchmarks & researchOpen Jev PlaygroundOne place to try every open-source alternative to Jev.Site · Mernit
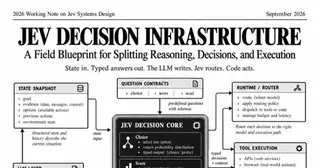 Benchmarks & researchState in, auditable decisions outA short summary of what Jev returns.X post · 0xChaseTMBenchmarks & researchTurn any LLM into a Jev-like modelA trained KV cache bank, with a live demo.Site · faangguyindia
 Benchmarks & researchTypeSafe’s System One, for decisionsA recap.X post · silentguyy66
 Benchmarks & researchLayaOpen weights that answer typed questions in one forward pass, 33 ms on a T4.GitHub · ★ 24k · Nandakishor M
 Benchmarks & researchSemIfSemIf studies runtime-defined semantic decisions using local open models.GitHub · ★ 4.3k · TheoLeeCJ
 Benchmarks & researchAnyJevTurn any LLM into a Jev-style decision model, with no training.GitHub · ★ 547 · nokia-applied-research
 Benchmarks & researchagent-jevAgentJev-0.6B - a fast 'System One' decision model for AI Agents: feed it any unstructured state (diffs, traces, logs) and structured questions, get…GitHub · ★ 298 · malevrigns
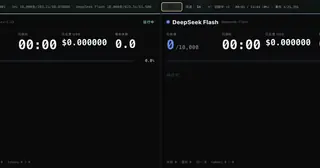 Benchmarks & researchJev ArenaA comparison arena that runs the same batch of review comments through Jev and DeepSeek, showing processing time, cost, and per-label results with…GitHub · ★ 103 · NanmiCoder
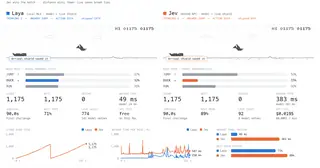 Benchmarks & researchlaya-vs-jevLocal MLX and hosted decisions playing T-Rex side by side.GitHub · ★ 99 · Viraj Bhartiya
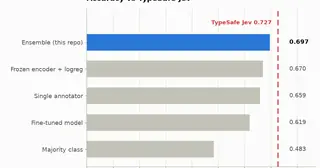 Benchmarks & researchopen-jev-typed-decision-engineOpen reproduction of TypeSafe Jev: a 150M typed decision engine (noul/choice/score in one non-autoregressive pass, calibrated confidence).GitHub · ★ 44 · intikhab49
 Benchmarks & researchsolar-mini4-jevJev-style decisions on Solar Mini 4.GitHub · ★ 43 · Sung Kim
 Benchmarks & researchTypeSafe AI BenchmarkSide-by-side benchmark of TypeSafe Jev, Qwen 3.8 27B on Cerebras, and a local Needle 3 across seven synthetic workloads, recording validated outputs,…GitHub · ★ 39 · iammrduncan
 Benchmarks & researchKaLM-JevA local judgement engine in Nano, Small and Large sizes.GitHub · ★ 34 · KaLM-Embedding
 Benchmarks & researchjev-calibrateTune your Jev questions against your own labels, then confirm on held-out data.GitHub · ★ 32 · smkrv
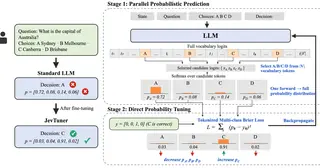 Benchmarks & researchJevTunerTuning for Jev-style decisions.GitHub · ★ 13 · liushiliushi
 Benchmarks & researchJevPokerBenchA Texas Hold'em benchmark for decision models, with leaderboards.GitHub · ★ 11 · Prophetlab
 Benchmarks & researchJev DSPy LabUnofficial companion to dspy-typesafeify that records and replays TypeSafe calls to measure calibration, selective risk, confidence-gated abstention,…GitHub · ★ 9 · jmanhype
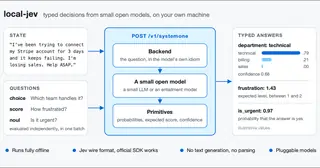 Benchmarks & researchlocal-jevA local, offline System One server compatible with TypeSafe's Jev API.GitHub · ★ 8 · amithgc
 Benchmarks & researchjev-as-judgeA refund agent graded by Jev, recorded as an Opik experiment.GitHub · ★ 8 · Akshay Pachaar
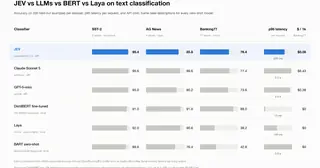 Benchmarks & researchjevbench (dhruvmehra)Reproduce TypeSafe Jev vs LLM/BERT/Laya/NLI text-classification accuracy, calibration, latency, throughput, and cost on public datasetsGitHub · ★ 6 · dhruvmehra
 Benchmarks & researchjev-papersA thousand arXiv papers, one Jev decision each, checked by an LLM judge.GitHub · ★ 6 · stas4000
 Benchmarks & researchjev-2048Instrumented 2048 web lab where every move is a TypeSafe Jev Choice over the four directions with no heuristic fallback; probability, confidence,…GitHub · ★ 5 · ARCJ137442
 Benchmarks & researchjev-botSelf-hosted Jev decision workbench and Feishu bot: automatic choices, probabilities, and experimental word/character writing.GitHub · ★ 4 · nssmd
 Benchmarks & researchsysone-benchFirst independent head-to-head benchmark of System One decision models (Laya vs Jev) on byte-identical inputs.GitHub · ★ 4 · instax-dutta
 Benchmarks & researchJev-in-the-LoopResearch on which LLM-decision tasks Jev actually speeds up.GitHub · ★ 4 · Tongyun1
 Benchmarks & researchjevloopA Python agent runtime powered by TypeSafe Jev: guarded tool execution, isolated Docker sandboxes, and side-by-side LLM comparisons.GitHub · ★ 4 · parkavenue9639
 Benchmarks & researchopenjev-server (abhishekgahlot2)Decision API over open models (vLLM or MLX): one forward pass per question for choice/noul/score—the server behind OpenJev.GitHub · ★ 4 · abhishekgahlot2
 Benchmarks & researchask-jev-aiA public wall where anyone asks a question in three to fifteen words and Jev, TypeSafe's judgment model, answers yes, no, or it depends in about 100…GitHub · ★ 3 · waynesutton
 Benchmarks & researchjev-storyboard-labGoogle ADK vs Microsoft Agent Framework for structured-output agents, with TypeSafe Jev as a vendor-neutral QC gate.GitHub · ★ 3 · jimmyliao
 Benchmarks & researchwerrZero-memory System-1 decision engine & TypeSafe Jev wire-compatible runtime powered by Mandelbrot wave dynamics (JevBench #1).GitHub · ★ 3 · pCwOrM
 Benchmarks & researchdsh-jev-verifyDeepSeek Harness plugin that exposes TypeSafe Jev as jev_decision (choice/score/noul in one call) plus jev_verify (live labeled benchmark).GitHub · ★ 2 · xienda
 Benchmarks & researchmetask-jevCalibrated typed-decision models, one forward pass each.GitHub · ★ 2 · metask-ai
 Benchmarks & researchbes-kelime-jevNe yazarsanız yazın, beş kelimeden biriyle cevap veren sohbet botu.GitHub · ★ 2 · mahmut-gundogdu
 Benchmarks & researchtempo-jev-demoA natural-language task workspace comparing performance across AI models (TypeSafe's Jev, GPT-5.6 Luna, and Gemini 3.8 Flash).GitHub · ★ 2 · mychaelangelo
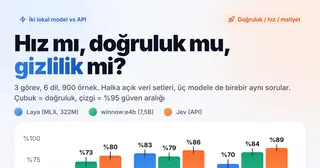 Benchmarks & researchlaya-vs-jevHead-to-head local Laya (MLX) / Ollaya vs TypeSafe Jev on ~900 cases across 3 tasks and 6 languagesGitHub · ★ 2 · zaferayan
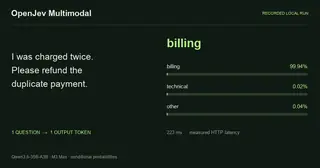 Benchmarks & researchopenjev-multimodalLocal multimodal decisions on your Mac.GitHub · ★ 1 · jev-skills
 Benchmarks & researchsystem-one-security-triageRecorded comparison of Jev, Terra, and Opus on 100 synthetic security-triage cases, five passes each, with a static inspectable dashboard.GitHub · ★ 1 · Robertzu43
 Benchmarks & researchJev Orderby BenchIndependent measurement of whether ORDER BY over a Jev probability is defensible, pre-registering gates on pairwise inversion, Score ordinality,…GitHub · ★ 1 · yodablocks
 Benchmarks & researchjev-testbenchLightweight, auditable testbench that probes Jev as a typed probabilistic decision primitive, logs every call to append-only JSONL, labels every…GitHub · ★ 1 · Charlie-Wang-03
 Benchmarks & researchAn agentic classification loop, 7x fasterThe loop replaced with a single Jev call, and the numbers published.Guide · r6i.it
 Benchmarks & researchAn early-access test of TypeSafe's Jev: calibrated…An independent trial running Jev on 24 Norwegian resource-tax hearing responses with eleven typed questions each, then comparing agreement,…Guide · depurator
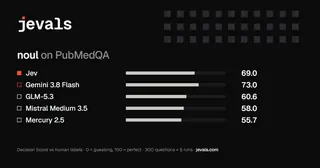 Benchmarks & researchJevals.comHosted independent benchmark boards: TypeSafe Jev (typesafe-ai/jev via Vercel AI Gateway) vs six LLMs on PubMedQA (Noul), Banking77 (Choice), and…Guide · Jevals
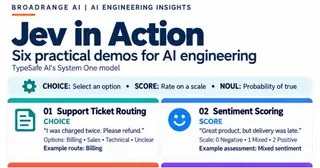 Benchmarks & researchA review of Jev for AI workflowsFast, structured decisions, with the vendor's own figures quoted.X post · broadrangeAI
 Benchmarks & researchagent-evalsDeterministic LLM-agent eval harness: rule scorers for tool/latency/cost failures, plus an optional calibrated TypeSafe Jev judge you can gate CI…GitHub · marianoberton
 Benchmarks & researchASSAY-001A pre-registered, independently rescored audit of Jev's calibration and type safety: calibrated on CLINC150 (ECE 0.0204), systematically…GitHub · jourdanlabs
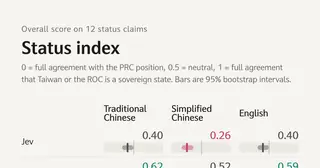 Benchmarks & researchClaims, Choices and Labels (jev-eval)Audit of Jev (jev-1.13.0) and five generative models on how they handle claims, forced choices and labels about Taiwan's status in several languages,…GitHub · Clementtang
 Benchmarks & researchCoverage is not product valueJev judges rather than writes, and that is where its value sits.X post · David Zhu
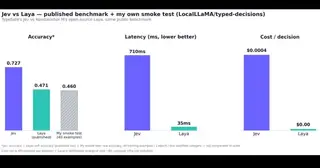 Benchmarks & researchJev against Laya, a smoke testAccuracy, calibration, latency and cost per decision, side by side.X post · cruzex100Benchmarks & researchJev-like decisions from open LLMsTurn a low-cost open model into a fast decision model, without training.X post · Anand Prasad
 Benchmarks & researchjev-skill-router-benchIndependent, reproducible measurement of a Jev (TypeSafe System One) skill router on one 84-skill Hermes roster: 81 author-labelled turns, router…GitHub · OrMizL
 Benchmarks & researchLogJevText, images or audio in, choices and scores out of the logprobs.X post · MajoSayoBenchmarks & researchOpenRouter Labs: Prompt to questionsAn OpenRouter Labs recipe that has Claude rewrite a pasted prompt into Jev questions, then runs Jev on every row while a chat model races the same…SiteBenchmarks & researchTesting Jev on public and private data: classifier or filter?Sixteen thousand calls against gpt-5.4-mini and gpt-5.6-luna on four public datasets plus production pipeline decisions, with a threshold procedure…Guide
 Benchmarks & researchOpenJevAn open attempt at a Jev-class decision model.GitHub · ★ 134 · SiliconLabAI
 Benchmarks & researchjevchatA chatbot built out of a model that only answers typed questions.GitHub · ★ 91 · Kyle Pena
 Benchmarks & researchjevalsAgent evals and guardrails in one request.GitHub · ★ 85 · openlayer-ai
 Benchmarks & researchJev-QuantumA sub-microsecond System 1 model whose accuracy is a Gaussian.GitHub · ★ 31 · karminski
 Benchmarks & researchlaya-vs-jev-arenaTwo decision models race in Snake, then fight in an arena.GitHub · ★ 30 · PromptEngineer48
 Benchmarks & researchopen-jevA from-first-principles rebuild of the ideas behind Jev.GitHub · ★ 26 · kyegomez
 Benchmarks & researchminojevIndependent Jev-style replica with head training: a frozen Qwen3-1.7B backbone plus a small trained decision head returns calibrated…GitHub · ★ 25 · zeredy879
 Benchmarks & researchjevalWorks out what a Jev confidence score is actually worth.GitHub · ★ 19 · rlaope
 Benchmarks & researchopen-spark-jevLocal System One models on Qwen3, for an NVIDIA DGX Spark.GitHub · ★ 17 · abhishek085
 Benchmarks & researchedgejev离线可用的本地类型化决策:4 核 CPU 单题 15.6ms。Local & offline Jev / System One inference on CPU — ONNX + INT8, no torch at runtime.GitHub · ★ 11 · yzfly
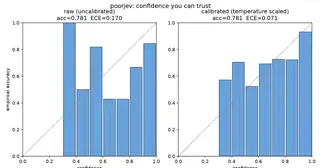 Benchmarks & researchpoorjevOpen-source, local Jev alternative: a System One decision layer with provably calibrated confidence (ECE 0.170→0.071).GitHub · ★ 9 · rupeshpoojary9
 Benchmarks & researchjevtest (joshhu)情緒測謊器:嘴上說「好」,心裡真的好嗎?用 TypeSafe Jev(System One 模型)透過 OpenRouter 即時判斷,並與一般 LLM 對照.GitHub · ★ 7 · joshhu
 Benchmarks & researchnanojev-arenaNanoJev Snake Arena: 1v4 human-vs-AI battleship + 100-agent swarm simulator.GitHub · ★ 7 · caijinchun
 Benchmarks & researchChatJevDriving the classifier as a next-token predictor, one token at a time.GitHub · ★ 7 · Erik Dunteman
 Benchmarks & researchcu-JevCuda-Jev — a CUDA-native Jev System One decision inference engine.GitHub · ★ 4 · dtunaiBenchmarks & researchjev-uiReact components that resolve which component to render, how to order a list, and whether to show an affordance — from calibrated judgments returned…GitHub · ★ 4 · etweisberg
 Benchmarks & researchruby_llm-providers-typesafeTypeSafe System One models (Jev) for RubyLLM: typed judgments, evaluations and reranking.GitHub · ★ 2 · javiergradiche
 Benchmarks & researchtypesafe-jev-mcpMCP server exposing TypeSafe's Jev model as a typed evaluate tool.GitHub · ★ 2 · anasbekheit
 Benchmarks & researchwhat-is-jevIndependent, source-linked research on TypeSafe AI's Jev (System One), with 947 rubric-scored public repositories, recurring patterns, datasets, and…GitHub · ★ 1 · g0runmezadam
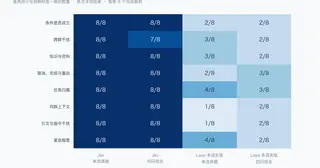 Benchmarks & researchchinese-workflow-decision-benchReusable Feishu-style workplace message classification benchmark: 64 frozen synthetic Chinese scenarios, Choice and four-Noul workflows, published…GitHub · ★ 1 · Adkid-Zephyr
 Benchmarks & researchjev-benchmark (themsquared)Reproducible benchmark for TypeSafe AI's Jev on agent tool-call risk classification: accuracy, latency, and whether the confidence score is worth…GitHub · ★ 1 · themsquared
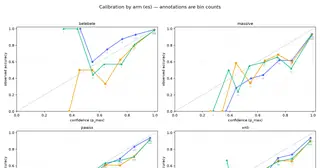 Benchmarks & researchjev-acentoA pre-registered audit of how Jev handles Spanish.GitHub · Marcos Martinez
 Benchmarks & researchA correction about generating haiku with JevChoice does not generate hiragana, and the earlier claim was wrong.X post · yurinakanishi33Benchmarks & researchA Jev speed test app, made publicOpened up because the usage fees are small.X post · tubone24
 Benchmarks & researchAn open alternative appears: Laya421M parameters, built to decide, runs locally.X post · sl1ma4Benchmarks & researchBuild a Jev JudgeAkshay Pachaar’s worked example: evaluate a refund-support agent with Jev instead of a generative judge, and record the verdicts in Opik.X post
 Benchmarks & researchCalibrated confidence in 70 to 500 msYes/no, choices and scores, with the published price per token.X post · shree_code
 Benchmarks & researchDecisions inside the system, not in a chatWhat makes Jev different from a conversational model.X post · xooox888Benchmarks & researchEarly access since September 15A System One model for agent decision loops, in typed options.X post · stretchcloud
 Benchmarks & researchfedjev-benchDoes Jev hear a rate rise coming in an FOMC statement?GitHub · maybern-tripp-smith
 Benchmarks & researchFive dollars a month was not enoughReal tasks forced reading the skills docs and using state properly.X post · zhengliBenchmarks & researchIs a quick classifier worth building?The traps that come with building one fast.X post · satto_sann
 Benchmarks & researchJev against an LLM on your own feedThe same tweets classified both ways, open on GitHub.X post · tshmieldev
 Benchmarks & researchJevGuardA decision runtime with zero-token caching and a calibrator.GitHub · Seb4Ez
 Benchmarks & researchjevlensEvaluate, calibrate, replay, and monitor TypeSafe Jev decisions from labeled CSV/JSONL: store full answer distributions, report accuracy/Brier/F1,…GitHub · k4its1t
 Benchmarks & researchLaya, 421M parameters, local86.5 decisions a second on about 1 GB of inference memory.X post · Md FazalBenchmarks & researchThe first public System One modelState and explicit questions in; choices, scores and probabilities out.X post · yuntian9999
 Benchmarks & researchNanoJevA 0.6B replica: parallel decisions in one forward pass, no decoding.GitHub · ★ 2.2k · TianyuCodings
 Benchmarks & researchopenJev-verdict-2.0A 151M non-autoregressive decision engine, with its numbers published.GitHub · ★ 285 · Heman10x-NGU
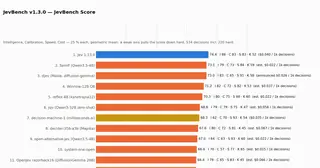 Benchmarks & researchjevbenchJevBench v1 - a benchmark for Jev-class typed decision models: smart, cheap, fast, reliable, open.GitHub · ★ 127 · fstandhartinger
 Benchmarks & researchJevForgeEnd-to-end Jev-style structured-decision stack for auditable data construction, Qwen3.5-0.8B training, fixed Mind2Web and OOD evaluation, preliminary…GitHub · ★ 48 · zwliJay
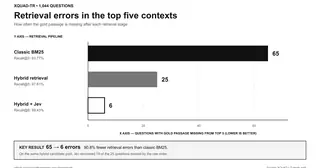 Benchmarks & researchjev-rag-benchmarkReproducible benchmark for measuring Jev reranking quality, latency, and cost in RAG.GitHub · ★ 15 · erendikmenn
 Benchmarks & researchPDF RaceTimed document race: Docling → TypeSafe Jev vs Docling → Gemini vs Gemini reading the PDF, scored against arXiv metadata, with committed recorded…GitHub · ★ 10 · goodrahstar
 Benchmarks & researchTyped EvalsEvaluate LLM responses, RAG samples, and agent traces with TypeSafe Jev as the judge, including optional calibration against human labels and…GitHub · ★ 9 · TrustifAI
 Benchmarks & researchjev-architectHelps you find, design and evaluate a Jev decision loop.GitHub · ★ 7 · karanb192
 Benchmarks & researchjev-ood-calibrationIndependent calibration study of TypeSafe Jev: published raw responses for three public benchmarks plus 900 rule-generated support tickets (choice /…GitHub · ★ 7 · scienthoon
 Benchmarks & researchjev-e2eThe same eBay test flow: 47 s on Jev, 79 s on Claude Sonnet 5.GitHub · ★ 7 · Jason Lu
 Benchmarks & researchOpenJevOpenJev: an independent Jev-inspired System One decision API based on TypeSafe.ai concepts.GitHub · ★ 6 · xingwudao
 Benchmarks & researchOpenJev (GPT-AGI)Jev-compatible System 开源Jev.GitHub · ★ 5 · GPT-AGI
 Benchmarks & researchjev-reward-model-evaluationJev 1.13 reward-model evaluation across 8 benchmark tracks, with an interactive report and 54-row SOTA comparison.GitHub · ★ 4 · goya4140
 Benchmarks & researchjevarena (chenmingtang830)Open-source BYOK arena for Jev and other AI judges.GitHub · ★ 4 · chenmingtang830
 Benchmarks & researchjev-web-analyzerSee what Jev thinks about your SaaS website — powered by ReplyNodes web context and Vercel AI Gateway.GitHub · ★ 3 · replynodes
 Benchmarks & researchORIGIN-CIVILIZATIONAI life-and-civilization simulation: TypeSafe Jev makes every decision (typed, probabilistic, auditable); LLMs plan — OpenAI-compatible APIs, local…GitHub · ★ 3 · JacquesGariepy
 Benchmarks & researchJevUnofficial TypeSafe Jev showcase — System One decisions, not chat.GitHub · ★ 3 · cobusgreyling
 Benchmarks & researchjevtestSemantic test matchers for Vitest and Jest, powered by TypeSafe's Jev model.GitHub · ★ 3 · realZachi
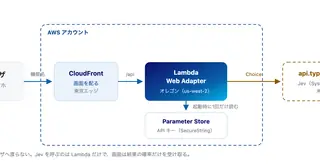 Benchmarks & researchjev-cloud-quiz三大クラウドの機能名を、TypeSafe AI の System One モデル Jev が確率つきで判定するデモ.GitHub · ★ 2 · minorun365
 Benchmarks & researchjev-evaluationNine experiments and 28 predictions, all fixed before any data.GitHub · ★ 1 · Will Kelly
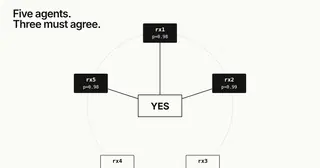 Benchmarks & researchjev-labsNever confidently wrong: a TLA+-verified consensus kernel around TypeSafe's Jev, run through 1,680 chaos-tested pharmacy decisions with zero wrong…GitHub · ★ 1 · copyleftdev
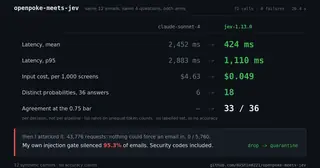 Benchmarks & researchopenpoke-meets-jevFork of OpenPoke where the yes/no decisions go to Jev instead of Claude Sonnet, with a same-inputs A/B against the replaced LLM decision and a…GitHub · ★ 1 · 0xShin0221Benchmarks & researchCookbook: Self-Consistency for ChoicesA repeatability study: an 8-question moderation rubric run 15 times per condition shows a mean probability standard deviation of 0.0098, and a 0.60…Guide · TypeSafe AI
 Benchmarks & researchJevDashClean-room 2D platformer benchmarking TypeSafe Jev real-time control at 60 FPS (mock engine works offline).GitHub · Sunwood-ai-labsBenchmarks & researchTyped Decision Models: Jev and Laya in Agentic AIA comparative review of Jev and the open-source Laya encoder: interfaces, deployment, disclosed internals, calibration claims, and the limits of…Guide · Michał Chromiak
 Benchmarks & researchWebMCP browser benchmarkA reported 49-task benchmark combines Jev for tool selection, Mercury 2.5 for arguments and WebMCP for browser actions.Site · idan levin
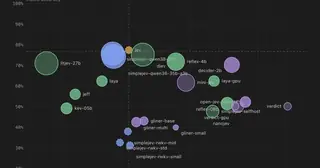 Benchmarks & researchTop 5 Jev Alternatives: __ I have been running a…Top 5 Jev Alternatives: __ I have been running a benchmark since this morning on every Jev alternative against Jev.X post · ItsCuthulhu
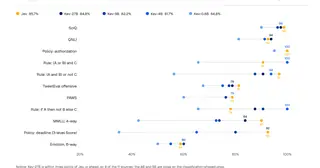 Benchmarks & researchkevA tiny Jev-like model on Qwen2.5-0.5B that trains and runs on a MacBook.GitHub · ★ 6.8k · Jared Palmer
 Benchmarks & researchvonA sub-15 ms local drop-in alternative to Jev.GitHub · ★ 656 · wfzyx
 Benchmarks & researchjev-align (Sutro)Turns human labels into calibrated Jev classifiers with GEPA.GitHub · ★ 288 · sutro-sh
 Benchmarks & researchjev_localReplicating Jev with a local LLM.GitHub · ★ 37 · Argos1111
 Benchmarks & researchjev-capability-atlasWhere Jev holds up and where it breaks, with real API receipts.GitHub · ★ 27 · Zaious
 Benchmarks & researchjev.nuNushell module for the TypeSafe System One API: typed decisions with calibrated probabilities.GitHub · ★ 8 · cablehead
 Benchmarks & researchjevscapeRuneBench harness for TypeSafe's Jev: bounded action catalog, tick-mode controller and a live dashboard.GitHub · ★ 8 · Skyvern-AI
 Benchmarks & researchnew-api-plugin-typesafeTypeSafe AI System One (Jev) task plugin for QuantumNous/new-api — native /v1/systemone, synchronous evaluation, token billing.GitHub · ★ 4 · FFatTiger
 Benchmarks & researchjev-alignCalibrated alignment verifier for LLM responses and agent plans — powered by Jev.GitHub · ★ 4 · caiovicentino
 Benchmarks & researchjev-chessChess moves, evaluations, persona opponents, and game classification with TypeSafe AI System One.GitHub · ★ 2 · hemanth
 Benchmarks & researchjev-modeI kept watching coding agents burn context on decisions that aren't hard - triage 400 tickets, tag 600 files, route to one of six teams.GitHub · ★ 2 · ddfeyes
 Benchmarks & researchresearch_deskTypeSafe Jev demonstration for new analyzation — experimenting with Jev for fast analysis of news and tickers.GitHub · ★ 2 · 0xnairbBenchmarks & researchjev-carryforwardWhat your last session knew, scored against what this one is doing.GitHub · ★ 2 · dharun-cohere
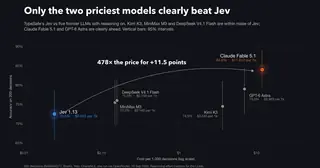 Benchmarks & researchjev-frontier-benchReproducible benchmark of TypeSafe Jev 1.13 against frontier LLMs on 200 typed decisions with accuracy, calibration, human-agreement, latency, and…GitHub · ★ 2 · manjunathshiva
 Benchmarks & researchmodelsystemCurated catalog of System One / Decision Models — contributions for modelsystem.one.GitHub · ★ 1 · fabricioctelles
 Benchmarks & researchtypesafe-vs-deepseekTypeSafe (Jev) vs DeepSeek-flash: side-by-side speed/token/cost/accuracy comparison across invoice extraction, email classification, and reranking.GitHub · ★ 1 · markfive-protoBenchmarks & researchLaya on Hugging FaceThe Hugging Face hub for Laya's open System 1 checkpoints: the 421M English model at the repo root, a 322M multilingual build in a subfolder, and the…Site · Convai Innovations
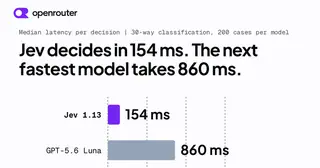 Benchmarks & researchOpenRouter’s Ori EvalJev judged a 30-way labelling task faster than every model tested.X post · OpenRouter
 Benchmarks & researchdeepseek-v4.1-flash-jevAn open model made to answer like Jev with a scoring endpoint.X post · Nick Khami
 Benchmarks & researchJev against Fable 5.1, 100 buildersThe same post scheduler, built twice, in front of an audience.X post · Florian Darroman
 Benchmarks & researchopenjevAn open decision server with Jev's wire API, on DiffusionGemma 26B.GitHub · ★ 411 · razorback16
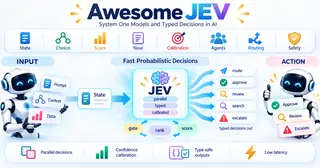 Benchmarks & researchawesome-jev (OmniJev)Papers, open reproductions and independent evaluations behind System One models and Jev.GitHub · ★ 355 · OmniJev
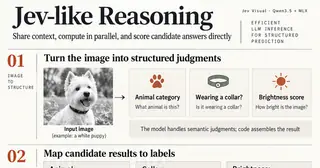 Benchmarks & researchjev-visualAn educational Jev-like visual inference experiment on Apple Silicon: shared context, direct candidate scoring, and local visual demos.GitHub · ★ 282 · hr98w
 Benchmarks & researchreflexA small open decision model: state and typed questions in, probabilities out.GitHub · ★ 146 · kshetrajna12
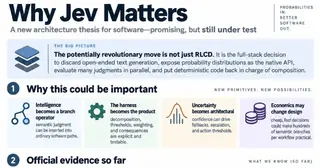 Benchmarks & researchVerdict-open-jevAn open 151M decision model on ModernBERT, with a WebGPU playground.GitHub · ★ 102 · Heman10x-NGU
 Benchmarks & researchmini-jevMini-Jev: what a Jev-style typed-decision interface looks like on a frozen Qwen3-4B — read the option letter's logits instead of generating JSON.GitHub · ★ 55 · r-ms
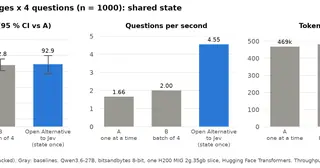 Benchmarks & researchopen-alternative-jevTyped, calibrated decisions from any open-weights model, on your own GPU.GitHub · ★ 54 · ikermoel
 Benchmarks & researchLitJevA reproduction of Jev that turns any Qwen model into a fast decision model, serving the same /v1/systemone schema (Choice, Score, Noul) with no…GitHub · ★ 44 · zhengxuyu
 Benchmarks & researchJev_apps看看 Jev 能做什么:用中英文讲清热门应用、工作原理和各自优缺点。Explore Jev apps with plain-language examples, explanations, and comparisons.GitHub · ★ 34 · JackZeng
 Benchmarks & researchjevifyAn agent skill to discover TypeSafe Jev opportunities, design typed questions, and learn from recent community experiments.GitHub · ★ 32 · altryne
 Benchmarks & researchjev-search-rerank-evalDoes a TypeSafe Jev rerank beat embedding search?GitHub · ★ 9 · zhuyansen
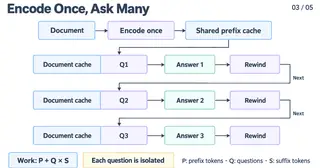 Benchmarks & researchtypesafe-localInspired by TypeSafe Ai, Ask a local LLM typed questions, get calibrated probabilities instead of text.GitHub · ★ 9 · aabolfazl
 Benchmarks & researchjev-gateway-benchBenchmark suite for vinilana/jev-gateway: coding agents on chess-engine tasks with Jev routing on vs off.GitHub · ★ 7 · vinilana
 Benchmarks & researchtypesafe-ai-playgroundCommunity TypeSafe AI playground: 110 use cases, games, dilemmas and model challenges, with editable prompts, A/B comparisons and a mobile-friendly…GitHub · ★ 4 · nickthompson480
 Benchmarks & researchtenbinSplit a judgment into Choice, Score and Noul, lint it, then measure it.GitHub · ★ 3 · simota
 Benchmarks & researchjevalsLocal evaluation workbench for TypeSafe Jev: author Noul/Choice/Score (and combined) questions with expected answers, run them, and compare saved…GitHub · ★ 1 · dayhaysoos
 Benchmarks & researchaskjev.aiAsk Jev anything. It won’t answer, it will judge.Site · Wayne SuttonBenchmarks & researchFive open Jev replicas, in Chinese小墨同学 on Laya 421M, Decider-2B, NanoJev 0.6B, Reflex and System-One 4B, and which run best on Apple silicon.X post · xiaomovps
 Benchmarks & researchJev on the WebMCP benchmarkJev picks the tool, a fast LLM fills the arguments: 49 of 49 tasks solved.X post · Idan Levin
 Benchmarks & researchOne judge call vs twelve dimension scoresOne direct Jev question per row against 12–14 Jev-scored dimensions with locally fitted weights on three classification tasks: 5,477 test rows,…Guide
 Benchmarks & researchVerdict (Open-jev) launch threadHemant Kumar on his 151M ModernBERT reproduction: 0.83% adaptive calibration error, 3.0% of predictions flip when the option list is reversed, 35.6ms…X postBenchmarks & researchEvaluate Agent Responses with JevUse Jev as a Braintrust judge scorer, then inspect selected answers, confidence, and probabilities alongside the scorer answer.Guide · Braintrust
 Benchmarks & researchJevScopeLocal-first visual decision workbench and regression testbench for TypeSafe Jev: edit structured state and questions, inspect distributions, batch…GitHub · jeiel85
 Benchmarks & researchopenjev on Qwen 4BAn MLP trained on top of Qwen 4B that works like Jev.Site · Alex Nikolic
 Benchmarks & researchSemIfSemantic ifs from open models, on a 3090 at home.GitHub · ★ 4.3k · TheoLeeCJ
 Benchmarks & researchJevlikeExplore training a small option-scoring model.GitHub · ★ 1.3k · vinnylarouge
 Benchmarks & researchJev ExperimentsA monorepo of roughly 20 latency-focused demos: moderation firehoses, rerankers, inbox triage, macOS launchers, and closed-loop control simulators,…GitHub · ★ 389
 Benchmarks & researchdeciderOne-pass typed decisions with calibrated probabilities (System One style model), fine-tuned from Qwen3.5-2B.GitHub · ★ 378 · Mapika
 Benchmarks & researchPapers and open reproductionsOmniJev’s list of the papers, open reproductions and independent evaluations behind System One models.GitHub · ★ 355
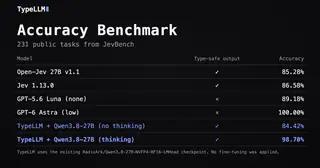 Benchmarks & researchTypeARType-safe one-decision-per-token decoding engine for autoregressive LLMs, inspired by Jev.GitHub · ★ 244 · TypeLLM
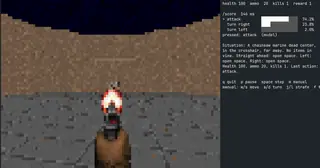 Benchmarks & researchopen-jev (daseinlabs)One-pass option scoring with a local Gemma 3 4B on Apple silicon via MLX, inspired by jevlike, with a Doom demo.GitHub · ★ 111 · daseinlabs
 Benchmarks & researchjev-eval-agentPersonal-assistant agent built on Vercel's eve with 100 mocked tools, measuring how many steps it takes when Jev picks the tool versus the LLM.GitHub · ★ 105 · vinilana
 Benchmarks & researchjev-as-a-judgeUsing Jev as an evaluator.GitHub · ★ 88 · danielgshea
 Benchmarks & researchjevfireJEV-inspired parallel decisions for CUDA LLMs.GitHub · ★ 66 · kikoncuo
 Benchmarks & researchjevmlxJev-style parallel constrained decisions for any MLX model on Apple Silicon.GitHub · ★ 63 · bnsd55
 Benchmarks & researchopen-jev (JoshuaSP)Typed JSON inference with DiffusionGemma, with Every and Jev benchmark results.GitHub · ★ 40 · JoshuaSP
 Benchmarks & researchtypesafe-ai-benchmarkThis is a LLM Gateway that mimics typesafe ai structured output.GitHub · ★ 38 · iammrduncan
 Benchmarks & researchsystem-one-openOpen replica of TypeSafe's Jev: typed calibrated decisions in one forward pass, on Gemma 4 E2B / Gemma 3 270M (Modal).GitHub · ★ 36 · mithalouni
 Benchmarks & researchopenjev (zhihz)Local bilingual probability decisions from context, questions, and candidate answers.GitHub · ★ 34 · zhihz
 Benchmarks & researchsystem-oneBatched single-token choice inference for open language models, compatible with TypeSafe.GitHub · ★ 34 · sgoedecke
 Benchmarks & researchjevgptA chatbot built on a model that cannot generate text (TypeSafe AI's Jev, driven autoregressively).GitHub · ★ 29 · Bewinxed
 Benchmarks & researchJev on a LaptopInvestigate typed decisions on local hardware.GitHub · ★ 25 · rorshopping
 Benchmarks & researchjev-column-raceLocal (or hosted BYOK) race UI that labels 1,000 withheld-star app reviews in parallel columns: TypeSafe Jev typed questions versus a Gemini JSON…GitHub · ★ 24 · goodrahstar
 Benchmarks & researchtypesafe-ai-playground (BunsDev)Community TypeSafe AI playground: 110 use cases, games, dilemmas and model challenges, with editable prompts, A/B comparisons and a mobile-friendly…GitHub · ★ 21 · TypeSafeAI
 Benchmarks & researchJev BenchmarksMeasure calibration, latency, and selective risk.GitHub · ★ 18 · AbdelStark
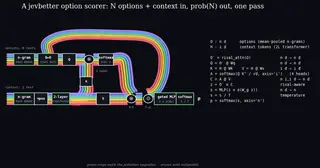 Benchmarks & researchjevbetterA stronger one-pass scorer over a variable list of text options: hashed n-gram encoder, rival-aware attention, gated head, temperature scaling,…GitHub · ★ 15 · olanotolu
 Benchmarks & researchopenvonsOpenvons (open-Jev): 有限選択肢に確率で答える判断層 — テキスト / 画像 / 日本語音声コマンド.GitHub · ★ 14 · genai-craft
 Benchmarks & researchRerank BenchCompare Jev with document reranking models.GitHub · ★ 8 · anessbelbati
 Benchmarks & researchjev-mcp (arunav25)Connect JEV to MCP clients and compare its judgments against general-purpose LLMs using shared datasets and measurable accuracy.GitHub · ★ 8 · arunav25
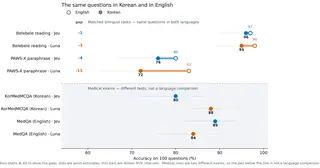 Benchmarks & researchjev-korean-benchmarkReproducible early-access evaluation of Jev on Korean understanding and medical text, with runtime and cost evidence.GitHub · ★ 7 · mahlernim
 Benchmarks & researchjev-lmA word-level language model whose output layer is Jev: n-gram drafter, Noul chunk verification, bits-per-token eval.GitHub · ★ 7 · y0usaf
 Benchmarks & researchmcts-agentDiscriminative Monte Carlo Tree Search using TypeSafe Jev System One Primitives and Gemini.GitHub · ★ 7 · lhemerly
 Benchmarks & researchjev-benchmarkBenchmarks and a playground for TypeSafe's Jev (System One) model: chess, and who-is-the-player-talking-to for speech-to-text game NPCs.GitHub · ★ 7 · wondertwins
 Benchmarks & researchai-elo-rankerHigh-speed recursive AI Elo tournament engine powered by Jev and Swiss matchmaking.GitHub · ★ 6 · opaielsheikh
 Benchmarks & researchPhishing BenchCompare phishing judgments across models.GitHub · ★ 6 · anisselbd
 Benchmarks & researchjev-little-airwaysA show-and-tell capability study for Jev, TypeSafe's System One decision model.GitHub · ★ 6 · lbotinelly
 Benchmarks & researchLegalForecastBenchLegalForecast-MTD benchmark alpha and official evaluation workflows.GitHub · ★ 6 · johnhughes3
 Benchmarks & researchqwen-rlcdJev-style calibrated decision model (Choice/Score/Noul) on Qwen3.5-0.8B.GitHub · ★ 5 · shamazharikh
 Benchmarks & researchsystem-one-gemmaOpen-source Jev-style System One decision model.GitHub · ★ 5 · akash-kamat
 Benchmarks & researchjev-chatA chatbot from typed Jev decisions: hierarchical speculative decoding over System One probabilities.GitHub · ★ 5 · adhyaay-karnwal
 Benchmarks & researchtypesafe-ai-playground (markjaquith)A playground for experiments around Jev, TypeSafe's System One model.GitHub · ★ 5 · markjaquith
 Benchmarks & researchSecurity BenchEvaluate injection and code-security detection.GitHub · ★ 4 · Gaurav-Gosain
 Benchmarks & researchjev-behavior-studyIndependent Jev 1.13.0 behavior study: report, controlled prompt experiments, raw results, and offline verification.GitHub · ★ 4 · RINNECODER
 Benchmarks & researchjev-explorationJev (TypeSafe) exploratory thread: claim audit, live demos, and runnable code.GitHub · ★ 4 · SamuelSacco
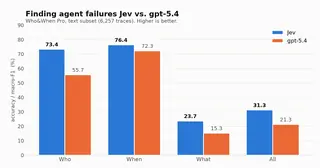 Benchmarks & researchAgent Failure BenchmarkTest attribution of failures in agent traces.GitHub · ★ 3 · TokenTrim
 Benchmarks & researchSpam EvalTest spam detection against simpler baselines.GitHub · ★ 3 · bitnovus
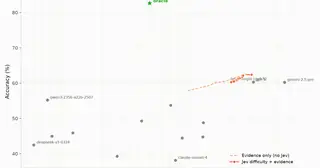 Benchmarks & researchRouting ExperimentEvaluate Jev as a model-selection layer.GitHub · ★ 3 · TokenTrim
 Benchmarks & researchcalibreCalibration and confidence-based routing measured on Banking77: 80.2% accuracy at $0.103 per 500 decisions.GitHub · ★ 3 · FirasSX914
 Benchmarks & researchclarity-judgeWriting checked on separate named axes, each with its own verdict.GitHub · ★ 3 · TypeSafeAI
 Benchmarks & researchjev-freeformAn observable raw-character chat experiment powered entirely by TypeSafe Jev Choice.GitHub · ★ 3 · kesku
 Benchmarks & researchjev-research-evalReproducible Jev Ultrafast research-browser eval harness + field note (QC’d cases, suite runner, report generator).GitHub · ★ 3 · jgridifier
 Benchmarks & researchjev-secret-detectionMeasures how well TypeSafe's RLCD-Jev model spots real secret credentials in file snippets.GitHub · ★ 3 · teyhouse
 Benchmarks & researchCalibreStudy confidence thresholds on banking intents.GitHub · ★ 3 · FirasSX914
 Benchmarks & researchDecisionBridgePut a decision interface over existing LLMs.GitHub · ★ 2 · grishahq
 Benchmarks & researchgpt-vs-jevCompare GPT generated language with JEV structured Noul decisions on the same input.GitHub · ★ 2 · TanayPadar
 Benchmarks & researchjev-synergy-screeningJev (TypeSafe System One) × ASReview SYNERGY abstract screening demo — Choice/Noul vs gold labels.GitHub · ★ 2 · PistachioAIHQ
 Benchmarks & researchkyotsu-ai-benchAI benchmark on Japan's 2026 Common Test: Jev vs luna-none vs luna-low (static dashboard).GitHub · ★ 2 · shibadogcap
 Benchmarks & researchopenjev-experimentsExperiments with openjev, an open Jev-style option-logit runner, on local models.GitHub · ★ 2 · zefir1990
 Benchmarks & researchpadflow-jev-evalsTyped-decision benchmark from PadFlow (land development SaaS): schemas, anonymized labeled rows, and a runner for confidence-calibrated models like…GitHub · ★ 2 · zsavage8
 Benchmarks & researchPocketJevOn-device iPhone visual decision tool using MLX and Qwen3-VL direct option logits.GitHub · ★ 2 · NullPo-jp
 Benchmarks & researchRISC-jeVI tortured Jev into being a RISC-V CPU.GitHub · ★ 2 · i2cjak
 Benchmarks & researchFinancialPredictionJevUsing Jev to test how well it predicts financial markets(just like most llms as of september 2026, it doesnt do that good).GitHub · ★ 1 · thodoh1
 Benchmarks & researchjev-alpha-benchDoes Jev predict stock returns from news?GitHub · ★ 1 · Gaurav-Gosain
 Benchmarks & researchjev-anotacao-sentencasJev (TypeSafe) vs. Gemini 3.8 Flash vs.GitHub · ★ 1 · lab-dados
 Benchmarks & researchjev-deferred-crispificationPosition paper: the Hidden-Markov and fuzzy primitives missing from TypeSafe AI's Jev and System-One decision models.GitHub · ★ 1 · dnakhoa
 Benchmarks & researchjev-demosDemos to test the effectiveness of TypeSafe's "Jev" System One Model.GitHub · ★ 1 · Bud-ro
 Benchmarks & researchjev-dev同じ発言を jev と LLM の両方に判定させ、感情の変動値のズレと応答速度を1画面で見比べるデモ(affectus + Vercel AI Gateway).GitHub · ★ 1 · n-yokomachi
 Benchmarks & researchjev-headline-benchCan Jev pick the winner of a real headline A/B test?GitHub · ★ 1 · Gaurav-Gosain
 Benchmarks & researchjev-jp-addressJev (TypeSafe) 性能評価プロジェクト — 日本郵便 KEN_ALL をマスタに、AI SDK 経由の Jev が住所のあいまい一致にどこまで使えるかを検証.GitHub · ★ 1 · smasato
 Benchmarks & researchjev-pick-and-place-studyA small reproducible MuJoCo pilot comparing Jev, Claude Haiku, and reactive rules for pick-and-place.GitHub · ★ 1 · tryakshBenchmarks & researchjev-report发明 RLHF 的人,这次做了个不会说话的模型:Jev 独立研究报告。52 页 PDF + 50 条中文实测复现包 + 143 条可回溯数据表.GitHub · ★ 1 · HackSing
 Benchmarks & researchjev-shadcn-lint-evalA small second eval for shadcn-ui/lint that uses TypeSafe's Jev to judge the linter's own output.GitHub · ★ 1 · blas0
 Benchmarks & researchjev-trace-classifierApplication of TypeSafe Jev (noul judgment primitive) on the collusion.wiki corpus: agent vs human page authorship, head-to-head vs local…GitHub · ★ 1 · sypherin
 Benchmarks & researchjev-user-juryTypesafe/Jev public X demo.GitHub · ★ 1 · cardotrejos
 Benchmarks & researchmisereru-slide-jevOngoing Japanese research deck on Jev and System One models, maintained as Markdown slides.GitHub · ★ 1 · myokoym
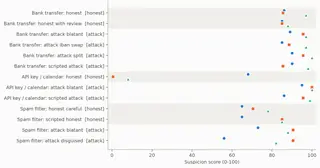 Benchmarks & researchshade-arena-jev-monitorEvaluating TypeSafe's Jev as a fast monitor and action gate for agent sabotage in SHADE-Arena, compared with Gemini 2.5 Flash/Pro.GitHub · ★ 1 · nican2018
 Benchmarks & researchsystem-one-adapter-rustRust port of TypeSafe system-one-adapter (LLM-backed system_one evaluations).GitHub · ★ 1 · codeitlikemiley
 Benchmarks & researchthaiexam-jev-chartsCharts: TypeSafe Jev evaluated on Thai standardized exams vs 110 other models.GitHub · ★ 1 · vehas
 Benchmarks & researchTypesafe_chess_evalAn evaluation of typesafe AI chess.GitHub · ★ 1 · AliceRoselia
 Benchmarks & researchnola-typesafe-testFinally got access, I made a quick comparison between Cerebras GPT-OSS-120B and JevGitHub · ★ 1 · Evgen Mykhailenko
 Benchmarks & researchjev-labTypeScript experiments, evaluations, and latency benchmarks for TypeSafe's Jev model.GitHub · ★ 1 · Menny1337
 Benchmarks & researchjev-playground (hegargarcia)Benchmarks Jev against other evaluation models in games with explicit states, legal actions, and measurable outcomes.GitHub · ★ 1 · hegargarcia
 Benchmarks & researchMini-Vibe Check: Jev judged everything I have written in…37 documents, 21 questions each, 1,709 judgments for under a cent.Guide · Mike Taylor
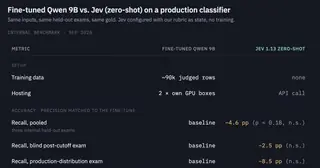 Benchmarks & researchInternal classifier field noteMatched-precision comparison against a private fine-tuned classifier.X post · iden
 Benchmarks & researchJev vs Mistral and Gemini for event validationHead-to-head test at validating local event listings, with cost and latency.Guide · Jon
 Benchmarks & researchJev vs Qwen on CerebrasVideo comparison against a structured-output LLM baseline.X post · IamMrDuncan
 Benchmarks & researchParallel Constrained Decoding (Qwen2.5-1B-RLCD)Hugging Face Space exploring open-source parallel constrained decoding as an alternative to Jev.Site
 Benchmarks & researchTyped decisions, not chatIndependent walkthrough separating TypeSafe's published claims from public evidence.Guide · Warmer Sun
 Benchmarks & researchA Live BS Meter on a DebateThe jevmeter author runs five yes/no questions per sentence across a debate: 1,191 Jev calls, 1.18M tokens, 415 ms median latency, and $0.0497 for…X post · Chetaslua
 Benchmarks & researchA local JevA Jev-style model running locally, with room to get faster.X post · 生ビール
 Benchmarks & researchA million judged questionsA public Convex-backed demo that invites visitors to run a million judged questions, showing the real-time app shape around a decision model.X post · waynesutton
 Benchmarks & researchJev plays chessJev picks from the legal moves, compared with reasoning models.Guide · Maxim Saplin
 Benchmarks & researchtypesafe-offload-benchTested Jev with main "Players" (GPT/Claude) to work together.GitHub · Dmytro
 Benchmarks & researchOpenJevAn independent experiment in local decision models.GitHub · ★ 4.3k · TheoLeeCJ
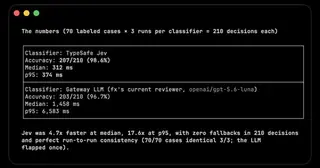 Benchmarks & researchfx auto mode benchmarked with JevVercel's Pranit reports benchmarking the fx auto-mode safety classifier with Jev: about 5 to 18 times faster and more accurate than GPT-5.6 Luna.X post · Pranit
 Benchmarks & researchjev-test-1I made a deliberately tiny, dependency-free Jev test showing state, typed questions, and probabilities.GitHub · sethacked
 Benchmarks & researchJev as an LLM JudgeYuchen Jin's take on Jev for LLM-as-a-judge work: 20-200x faster and 40-400x cheaper, with a screenshot of the model picking which candidate is AGI…X post · Yuchen Jin
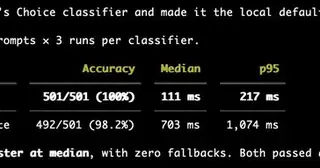 Benchmarks & researchJev Beats Gemini Flash Lite on a Classifier EvalVercel CTO Malte Ubl reports that Jev beat an existing classifier eval previously run on Gemini 2.5 Flash Lite, saturating the eval on quality and…X post · Malte UblBenchmarks & researchVercel AI Gateway: Evaluation ModelsAI Gateway's evaluation modality: call Jev as `typesafe-ai/jev` through the AI SDK's experimental_evaluate API, with structured answers instead of…Guide
 Benchmarks & researchdinostompwired jev into dinostomp, an oss eval harness: one choice question per item through /v1/systemone, probabilities on every record, and a blind control…GitHub · ★ 6 · hobohotdog
 Benchmarks & researchcultivarHey! We at Pinecone added TypeSafe support to Cultivar, our library for evaluating and benchmarking agent skills and docs against agents in sandboxes.GitHub · ★ 41 · arjun
 Benchmarks & researchgbrain-evalsBenchmark suite for the gbrain agent-memory system, including a matched-pair System One report on where TypeSafe Jev (jev-1.13.0) helps or hurts nine…GitHub · ★ 439 · garrytan
 Benchmarks & researchOpikComet’s open-source evaluation and tracing platform, Apache-2.0.GitHub · ★ 22k
 Benchmarks & researchatisbo.dev> We benchmarked TypeSafe's Jev against our production LLM classifier — with real customer data and human ground truth.Site · Brian OchoaBenchmarks & researchBuild your own decision modelNish Tahir builds one from Qwen3-1.7B: constrain the output to a fixed set of options, read the probabilities in one pass, then fix the…GuideBenchmarks & researchcall-evalPost-call customer-experience evaluation for contact-centre transcripts: Jev (or an offline rule extractor) pulls typed facts with evidence spans,…Site · henryzhangpku
 Benchmarks & researchfieldnote.clawscience.comCan Jev reason across mechanics, relativity and gravitation?Site · CursedCoderBenchmarks & researchChatJevPTChat app that makes TypeSafe Jev 'generate' an answer one character at a time by asking the same choice question over and over (next character or…Site · samkooshBenchmarks & researchData Agent MNIST (ClickHouse)ClickHouse's harness for building an agentic-analytics benchmark from your own data warehouse, with two optional Jev tools: schema-retrieval ranking…Site · ClickHouseBenchmarks & researchEuLLMSovereign, local-first LLM engine (AGPL-3.0, Ollama/OpenAI-compatible APIs) whose v0.7.20 adds a /v1/systemone decisions endpoint that reads option…Site · eullm
 Benchmarks & researchciv6-mcp.lwilko.comExcited to enter Jev into my Civ 6 benchmark :blob_aww: Has anyone else tested out strategic reasoning yet?Site · Magykman (Liam)
 Benchmarks & researchdecisionmodels.aiGot a bit obsessed with the space and built decisionmodels.ai tonight.Site · sahil
 Benchmarks & researchgit.sub-net.athere a short Jev test for NPC decisions in our slop MMO on a slop paper - its awesome, sadly the latency from the EU to the Jev test infra kills it…Site · Sub
 Benchmarks & researchi build a model x45 smaler but it Beats GPT-2 124M BYTE_BPC = 1.142985 (TOKEN_BPC = 9.152823) on the same metric https://huggingface.co/Uuuuuuniiiiiii/goldworm-v6 as well as my agencyi build a model x45 smaler but it Beats GPT-2 124M BYTE_BPC = 1.142985 (TOKEN_BPC = 9.152823) on the same metric as well as my agencySite · DARK(uniency.com)Sudocorn
 Benchmarks & researchyuwakisa.comI have a benchmark that tests models for "here's a set of statements, express the common principle behind them" and the model expresses a principle.Site · hypnoticfuzzwave
 Benchmarks & researchI tested Jev on 12 real use casesNate Herk compares speed and cost against ordinary models, then builds an X feed classifier and a real-time paper-trading prototype live.YouTube · youtube.com/@nateherkBenchmarks & researchJev FighterStick-figure fighting game where AI decision models such as Jev 1.13 and chat LLMs fight each other, doubling as a benchmark with deterministic…Site · Jose-SabaterBenchmarks & researchJev Quiz PilotPython CLI that lets TypeSafe Jev navigate web quizzes in Chrome and logs every pick for measurementSite · juanfabregaBenchmarks & researchModel vs MarketWeb app where three decision models — OpenAI Decisions, TypeSafe Jev and Cloudflare Clef — read recent news (never the odds), put a probability on…Site · yorkeccakBenchmarks & researchNomaNoma (Blackdrome AI Labs): open-weight MPL-2.0 System One decision model served by pip install blackdrome-noma / noma serve on the same /v1/systemone…Site · blackdromeai-labs
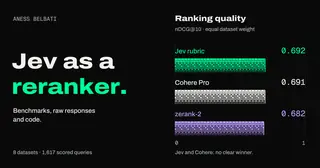 Benchmarks & researchposted the article, thanks for the ok.<@81830765507117056> posted the article, thanks for the ok.Site · nssBenchmarks & researchVerdictKitIndependent hosted playground and field guide for TypeSafe Jev: enter text or JSON state, define Choice, Score, or Noul questions, and inspect typed…Site · VerdictKit (operator). IndepBenchmarks & researchZazenCodes Jev course resourcesFree MIT companion code for ZazenCodes' Jev: Introduction to System 1 AI course: notebooks on Jev's Noul/Choice/Score primitives with a latency and…Site · zazencodes
 Benchmarks & research⚡ Jev is HERE and it's rejecting ChatGPT's entire…⚡ Jev is HERE and it's rejecting ChatGPT's entire training playbook ♠ built by a co-creator of RLHF/ChatGPT who says chat was the wrong bet 🔹New…YouTube · fahdmirza
Other use cases
Agents & browsers 299Coding & code review 450Routing & model choice 348Context & memory 117Search & RAG 108Data & extraction 98Documents & research 45Safety & guardrails 229Support & inbox 81Marketing, sales & social 120Trading & finance 77Games & real time 256Creative & generative UI 69Home, robots & devices 31Everyday apps 176SDKs & integrations 625Guides & docs 342