Repo · Benchmarks & research
jev-judge
Pytest/Vitest-style CI evaluations of LLM and RAG outputs: declarative YAML tests (faithfulness, relevance, hallucination, guardrails) answered by…
Open github.com ↗From the repository
Vitest for LLM outputs. Sub-100ms, deterministic CI/CD evaluations powered by TypeSafe Jev.
ai-agentsci-cdevalsjevllm-as-a-judgeragtestingtypesafevitest
How builders describe it
Pytest/Vitest-style CI evaluations of LLM and RAG outputs: declarative YAML tests (faithfulness, relevance, hallucination, guardrails) answered by TypeSafe Jev noul/score questions instead of an LLM-as-a-judge, with JSON/Markdown reports and an MCP server.
Python CLI that runs declarative YAML, JSON or JSONL test suites natively on Jev Noul, Choice and Score decisions for RAG faithfulness, hallucination detection and agent safety, with watch mode, parallel batching, a pytest plugin and GitHub Actions PR reporting.
The decision Jev makes
Benchmark questions with known answers, to check accuracy and confidence.
Where it fits
Head-to-head tests, calibration studies and independent research into how well Jev decides, how fast, and at what cost. All 682 benchmarks & research projects →
Related projects
 Benchmarks & researchMicaA 4B decision model: calibrated probabilities for yes/no, choice and score questions over long inputs.GitHub · ★ 37 · akivet
 Benchmarks & researchawesome-jev-papers📄 Research papers on Jev, TypeSafe's System One model, and the open models built in its shape.GitHub · ★ 5 · OmniJev
 Benchmarks & researchjev-typesafe-real-financial-use-casesFifty real-world financial use cases for TypeSafe's Jev model: typed, structured LLM answers over ledgers, fraud, portfolios, trades and filings,…GitHub · ★ 3 · IslamBaraka90
 Benchmarks & researchjev-healthcare-labOpen experiment comparing TypeSafe Jev vs DeepSeek on 96 healthcare tasks across 12 scenarios (quality, latency, cost) with per-task data and…GitHub · JuneYaooo
 Benchmarks & researchtypesafe-jev-ecosystemExplore the TypeSafe Jev ecosystem: open-source integrations, compatible decision models, SDKs, agent tools, and research.GitHub · ★ 4 · VoltAgent
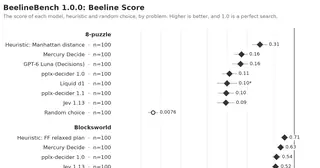 Benchmarks & researchBeelineBenchHow well do decision models plan across a multi-step problem?GitHub · ★ 3 · kyle-pena-nlp