Repo · Benchmarks & research
jev-security-prioritization
Reproducible experiment: TypeSafe Jev prioritizes SCA/SAST findings using richer context than severity scores, compared to severity-only and points…
Open github.com ↗How builders describe it
Reproducible experiment: TypeSafe Jev prioritizes SCA/SAST findings using richer context than severity scores, compared to severity-only and points baselines via OpenRouter Decisions.
The decision Jev makes
Benchmark questions with known answers, to check accuracy and confidence.
Where it fits
Head-to-head tests, calibration studies and independent research into how well Jev decides, how fast, and at what cost. All 332 benchmarks & research projects →
Related projects
 Benchmarks & researchJev 1.13.0 against Hopper on Benchmark HeavenHopper wins three columns, Jev keeps Intelligence.Site · Benchmark Heaven
 Benchmarks & researchValenTrain a Jev-like multimodal model by yourself.GitHub · ★ 51 · Liuziyu77
 Benchmarks & researchjev-dimabsaTypeSafe Jev baseline for DimABSA (SemEval-2026 Task 3) subtask 1: zero-shot and 3-shot valence-arousal regression.GitHub · ★ 6 · ZhangYiqun018
 Benchmarks & researchreflexbenchReflexBench — open benchmark and evaluation harness for System One models and typed decision engines.GitHub · ★ 4 · brida-ai
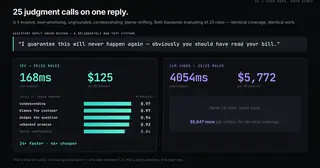 Benchmarks & researchjev-guardrailsResearch/eval repo that runs the same mock carrier support agent and 25 behavioural guardrail rules behind two backends—chat-model JSON judge vs…GitHub · ★ 3 · deepansh-saxena
 Benchmarks & researchtypesafe-jev-calibrate-for-code-reviewAbout calibrating Jev for code reviews.GitHub · ★ 3 · Selmar