Repo · Benchmarks & research
jev (taifoon-io)
Grade an AI agent job with TypeSafe Jev: fact checks in code, four closed questions, receipt with probabilities, optional on-chain records…
Open github.com ↗From the repository
Grade an AI agent's job with TypeSafe's Jev: did it do the work as the task laid it out? Facts first, Jev on your own key, a receipt, and optional on-chain records.
agent-evaluationagentic-commerceai-agentsbaseerc-8183graderjevllm-as-a-judgetypesafe
How builders describe it
Grade an AI agent job with TypeSafe Jev: fact checks in code, four closed questions, receipt with probabilities, optional on-chain records (@taifoon/jev)
The decision Jev makes
Benchmark questions with known answers, to check accuracy and confidence.
Where it fits
Head-to-head tests, calibration studies and independent research into how well Jev decides, how fast, and at what cost. All 682 benchmarks & research projects →
Related projects
 Benchmarks & researchMicaA 4B decision model: calibrated probabilities for yes/no, choice and score questions over long inputs.GitHub · ★ 37 · akivet
 Benchmarks & researchawesome-jev-papers📄 Research papers on Jev, TypeSafe's System One model, and the open models built in its shape.GitHub · ★ 5 · OmniJev
 Benchmarks & researchjev-typesafe-real-financial-use-casesFifty real-world financial use cases for TypeSafe's Jev model: typed, structured LLM answers over ledgers, fraud, portfolios, trades and filings,…GitHub · ★ 3 · IslamBaraka90
 Benchmarks & researchjev-healthcare-labOpen experiment comparing TypeSafe Jev vs DeepSeek on 96 healthcare tasks across 12 scenarios (quality, latency, cost) with per-task data and…GitHub · JuneYaooo
 Benchmarks & researchtypesafe-jev-ecosystemExplore the TypeSafe Jev ecosystem: open-source integrations, compatible decision models, SDKs, agent tools, and research.GitHub · ★ 4 · VoltAgent
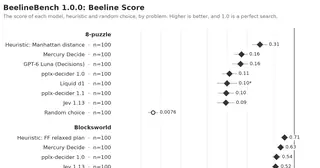 Benchmarks & researchBeelineBenchHow well do decision models plan across a multi-step problem?GitHub · ★ 3 · kyle-pena-nlp