Repo · Benchmarks & research
Rerank Bench
Compare Jev with document reranking models.
Open github.com ↗From the repository
Can a decision model beat dedicated rerankers? TypeSafe Jev vs Cohere Rerank 4 vs ZeroEntropy zerank-2 vs a chat-model baseline: 14 datasets, every raw API response, bootstrap ranges on every gap.
benchmarkcohereinformation-retrievalllm-evaluationndcgragrerankerrerankingtypesafezeroentropy
How builders describe it
Can a decision model beat dedicated rerankers? TypeSafe Jev vs Cohere Rerank 4 vs ZeroEntropy zerank-2 vs a chat-model baseline: 14 datasets, every raw API response, bootstrap ranges on every gap.
Reproducible experiments comparing TypeSafe Jev rubric/Choice reranking recipes against Cohere, ZeroEntropy, and open rerankers on shared BM25 candidate sets.
Reranking benchmark that gave Jev, Cohere Rerank 4 Pro, ZeroEntropy zerank-2, and DeepSeek the same thirty BM25 candidates across eight English datasets, publishing saved responses, scoring code, and paired-bootstrap intervals. Jev's rubric scored 0.692 nDCG@10 against Cohere Pro's 0.691.
The decision Jev makes
Benchmark questions with known answers, to check accuracy and confidence.
Where it fits
Head-to-head tests, calibration studies and independent research into how well Jev decides, how fast, and at what cost. All 682 benchmarks & research projects →
Related projects
 Benchmarks & researchMicaA 4B decision model: calibrated probabilities for yes/no, choice and score questions over long inputs.GitHub · ★ 37 · akivet
 Benchmarks & researchawesome-jev-papers📄 Research papers on Jev, TypeSafe's System One model, and the open models built in its shape.GitHub · ★ 5 · OmniJev
 Benchmarks & researchjev-typesafe-real-financial-use-casesFifty real-world financial use cases for TypeSafe's Jev model: typed, structured LLM answers over ledgers, fraud, portfolios, trades and filings,…GitHub · ★ 3 · IslamBaraka90
 Benchmarks & researchjev-healthcare-labOpen experiment comparing TypeSafe Jev vs DeepSeek on 96 healthcare tasks across 12 scenarios (quality, latency, cost) with per-task data and…GitHub · JuneYaooo
 Benchmarks & researchtypesafe-jev-ecosystemExplore the TypeSafe Jev ecosystem: open-source integrations, compatible decision models, SDKs, agent tools, and research.GitHub · ★ 4 · VoltAgent
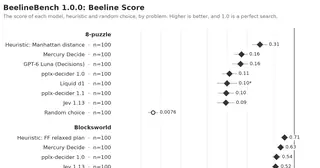 Benchmarks & researchBeelineBenchHow well do decision models plan across a multi-step problem?GitHub · ★ 3 · kyle-pena-nlp