Repo · Benchmarks & research
tenbin
Split a judgment into Choice, Score and Noul, lint it, then measure it.
Open github.com ↗From the repository
MCP server and agent skill for the TypeSafe AI System One API (Jev): decompose a judgment into Choice / Score / Noul questions, lint them, measure on labelled data, and put calibrated thresholds in code
agent-skillcalibrationclassificationclaude-codeconfidencejevllmmcpmcp-serverpythonsystem-onetypesafe-aitypescript
How builders describe it
MCP server and agent skill for the TypeSafe AI System One API (Jev): decompose a judgment into Choice / Score / Noul questions, lint them, measure on labelled data, and put calibrated thresholds in code.
Design-time toolkit for using Jev from a coding agent, combining docs, a stdio MCP server, and an agent skill for decomposing judgments into Choice, Score, and Noul.
The decision Jev makes
Benchmark questions with known answers, to check accuracy and confidence.
Where it fits
Head-to-head tests, calibration studies and independent research into how well Jev decides, how fast, and at what cost. All 682 benchmarks & research projects →
Related projects
 Benchmarks & researchMicaA 4B decision model: calibrated probabilities for yes/no, choice and score questions over long inputs.GitHub · ★ 37 · akivet
 Benchmarks & researchawesome-jev-papers📄 Research papers on Jev, TypeSafe's System One model, and the open models built in its shape.GitHub · ★ 5 · OmniJev
 Benchmarks & researchjev-typesafe-real-financial-use-casesFifty real-world financial use cases for TypeSafe's Jev model: typed, structured LLM answers over ledgers, fraud, portfolios, trades and filings,…GitHub · ★ 3 · IslamBaraka90
 Benchmarks & researchjev-healthcare-labOpen experiment comparing TypeSafe Jev vs DeepSeek on 96 healthcare tasks across 12 scenarios (quality, latency, cost) with per-task data and…GitHub · JuneYaooo
 Benchmarks & researchtypesafe-jev-ecosystemExplore the TypeSafe Jev ecosystem: open-source integrations, compatible decision models, SDKs, agent tools, and research.GitHub · ★ 4 · VoltAgent
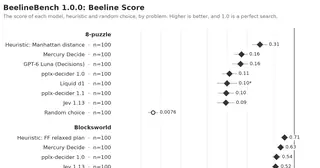 Benchmarks & researchBeelineBenchHow well do decision models plan across a multi-step problem?GitHub · ★ 3 · kyle-pena-nlp