Jev as a judge: evaluating LLM and agent outputs
Yes, Jev can judge LLM and agent outputs: you send the output as the state, ask typed questions about it, and get back answers with probabilities instead of a written verdict (System One). It does not write critiques or explain its reasoning, so it works best when you split a rubric into narrow questions and combine the answers in code (Primitives).
Why a decision model fits evaluation
An LLM judge reads an output and writes an assessment that you then parse. Jev skips the writing. It returns a choice, a score on levels you define, or a noul between 0 and 1 for a yes/no question (Primitives). New to the model? Start with What is Jev?
A few documented properties matter for evals:
- Questions in one request are evaluated independently and in parallel, so one answer does not become hidden context for another (How to build with TypeSafe).
- Most queries complete in about 100 ms (How to build with TypeSafe).
- Jev is charged per input token at $0.042 per million, and output tokens are free (Models). See Jev pricing.
- Its probabilities are trained to be calibrated, but calibration is measured across groups of predictions and does not guarantee that any single answer is correct (System One).
TypeSafe lists "universal verification" as a use case: checking prompts, extractions, reasoning traces and tool calls from other AIs for errors such as citation mistakes and hallucinations (Example use cases).
What the docs say about consistency
Repeatability is a common complaint about LLM judges. TypeSafe ran one insurance claim through a 14-question Noul rubric 15 times. Jev's mean per-question standard deviation was 0.0102, below every LLM probability condition in that run, but answers to one question still ranged from 0.43 to 0.53, crossing a 0.5 threshold (Self-consistency: nouls).
A second run used 8 Choice questions on one borderline post. Jev repeated its most common label 90.8% of the time, against 87.5% to 100% for the LLM settings, and flipped on 2 of 8 questions. With a rule that sends answers below a 0.60 top probability to human review, agreement rose to 99.2%, with 74.2% of answers labelled automatically (Self-consistency: choices).
Both are single-example tests from TypeSafe itself. A stable judge can still be consistently wrong, so check it against your own human labels. For a wider comparison, read Jev vs. LLMs.
A documented pattern: split, score, gate
TypeSafe's advice is one snap judgment per question. Instead of "rate this startup pitch", ask about each factor separately and weight the answers in code (Primitives). The composite scoring pattern normalises each Score and combines them with weights you can change without rewording questions (Composite scoring).
Then gate on confidence. The docs suggest three bands: act when confidence is high, proceed with caution in the middle, and route to a person when it is low. Thresholds should rise with the cost of a wrong call (Confidence).
Two cookbooks show this for verification:
- Citation checking runs a plain string match first, then one Choice question decides whether the quoted section supports, contradicts or says nothing about the claim. Verdicts below 0.8 confidence go to a person (Double-checking citations).
- LLM guardrails ask one Noul per hazard plus a Score for how much harm complying would do, and code decides pass, review, block or route (Guardrails for LLMs).
Question designs for an eval rubric
Put the trace in the state as JSON and name the part each question is about with a backticked path, such as `answer` or `tool_calls[2]`, so the model knows what to judge (Primitives).
- Noul: "Is the claim in
`claims[0]`supported by`retrieved_passages`?" Ask one condition per Noul and combine them in code (Noul). - Choice: how the cited source relates to the claim: supports, contradicts, or says nothing (Double-checking citations). Add an
otheroption when your list may not cover every case (Primitives). - Score: helpfulness or completeness on 2 to 10 levels, each described in words. Each level is judged on its own against the state (Score).
More worked examples live under Benchmarks and research and Safety and guardrails. For setup, see How to use Jev.
Limits to plan for
TypeSafe's jaggedness notes for jev-1.13 apply directly to judging (Jev 1.13 jaggedness):
- It reads instructions literally, so write the exact condition and put boundary cases in the criteria.
- It does not count reliably or do arithmetic well. Count claims or compute metrics in code.
- Accuracy falls as the state fills with unrelated detail. Send only what the question needs.
- Content written to steer the model, such as an injected instruction inside the output being judged, can move the answer.
- It is not trained to generate text. If you need a written critique for a developer, use an LLM for that part.
Projects doing this
 Benchmarks & researchjev-as-a-judgeCompares Jev with LLM judges on the same fixed agent runs, measuring accuracy, score reliability, cost and latency.GitHub · ★ 83 · danielgshea
 Benchmarks & researchjevalsRuns agent evals and guardrails in one request, built on Jev, Kev and Laya.GitHub · ★ 82 · openlayer-ai
 Coding & code reviewpi-jev (y0usaf)Adds a pre-tool gate, a post-tool output judge and a typed jev_ask tool to the Pi coding agent.GitHub · ★ 144 · y0usaf
 Benchmarks & researchjev-as-judgeGrades a refund-support agent with Jev and records the results as an Opik experiment.GitHub · Akshay PachaarBenchmarks & researchBuild a Jev JudgeAkshay Pachaar's worked example of evaluating a refund-support agent with Jev instead of a generative judge.X post
 Benchmarks & researchTyped EvalsEvaluates LLM responses, RAG samples and agent traces with Jev as the judge, with optional calibration against human labels.GitHub · TrustifAI
 Benchmarks & researchagent-evalsAn agent eval harness with rule-based scorers plus an optional Jev judge you can gate CI deploys on.GitHub · marianoberton
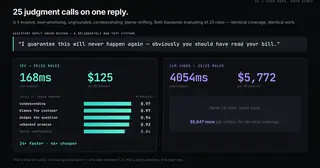 Benchmarks & researchjev-guardrailsRuns the same agent and 25 guardrail rules behind a chat-model JSON judge and behind Jev to compare cost, latency and coverage.GitHub · ★ 3 · deepansh-saxena
 Benchmarks & researchclarity-judgeChecks writing quality on separate named axes, each with its own verdict and confidence.GitHub · ★ 2 · TypeSafeAI
 Benchmarks & researchOne judge call vs twelve dimension scoresCompares one direct Jev question per row with 12 to 14 Jev-scored dimensions and fitted weights across three classification tasks.Site
Questions
Can Jev replace an LLM-as-a-judge?
For checks you can phrase as typed questions, such as grounded or not, correct tool or not, or a rubric score, it can. It cannot write a critique or explain its reasoning, so keep an LLM where you need written feedback.
Does Jev explain why it gave a score?
No. TypeSafe says System One models do not generate explanations of their reasoning. You get probabilities for each option or level, which you can log and inspect instead.
Is a calibrated judge always right?
No. TypeSafe says calibration is measured across groups of predictions and does not guarantee that an individual answer is correct. Compare the judge with human labels on your own data before trusting it.
How much does it cost to run evals with Jev?
The TypeSafe models page lists jev-1.13 at $0.042 per million input tokens, with output tokens free. Asking many questions in one request shares a single state, so cost is mostly the size of the trace you send.
Can Jev judge screenshots or images?
Not directly. Jev accepts text only: a string, a JSON object or an array of text. Convert other inputs to text first.
More guides: What is Jev?Jev pricing and API costJev vs LLMs: when to use whichHow to use Jev: a quickstartJev and MCP: using Jev as a Model Context Protocol toolHow to use Jev with Claude CodeJev in an agentic harness: where it fits in an agent loopJev for orchestration: routing requests, models and skillsJev for SEO and GEOJev for ads and ad reviewJev for marketing and lead scoringIs there an open source Jev?Can you fine-tune Jev?Designing questions for JevWhat is RLCD?Jev statistics